#include <fft_grid.hpp>
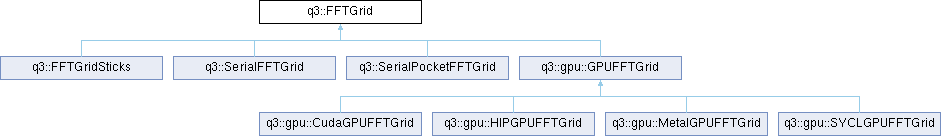
 Inheritance diagram for q3::FFTGrid:
Public Member Functions | |
| virtual | ~FFTGrid ()=default |
| virtual void | assign_sticks (const std::vector< int > &) |
| virtual bool | co_locates_mirrors () const |
| virtual int | concurrent_transform_slots () const |
| virtual void | execute_forward_on_buffers () const =0 |
| virtual void | execute_forward_on_slot (int) const |
Forward transform on slot slot, the slot-aware execute_forward_on_buffers(). | |
| virtual void | execute_inverse_raw_on_buffers () const =0 |
| virtual void | execute_inverse_raw_on_slot (int) const |
Inverse transform on slot slot, the slot-aware execute_inverse_raw_on_buffers(). | |
| virtual void | forward (Complex *data) const =0 |
| virtual void | forward_batched (Complex *data, int batch_size) const |
| virtual int | g_vector_to_fft_grid_index (int miller_1, int miller_2, int miller_3) const =0 |
| virtual void | gather_local_g_space (const Complex *full_g_space, Complex *local_g_space) const |
| virtual int | global_real_space_index (int local_index) const |
| virtual int | grid_dimension_1 () const =0 |
| virtual int | grid_dimension_2 () const =0 |
| virtual int | grid_dimension_3 () const =0 |
| virtual void | init (int dimension_1, int dimension_2, int dimension_3, bool use_measured_planning=false)=0 |
| virtual void | initialize_batched_plans (int, bool=false) const |
| virtual int | initialized_batched_plan_size () const |
| virtual Complex * | input_buffer () const =0 |
| virtual void | inverse (Complex *data) const =0 |
| virtual void | inverse_raw (Complex *data) const =0 |
| virtual void | inverse_raw_batched (Complex *data, int batch_size) const |
| virtual void | inverse_raw_on_slot (Complex *data, int) const |
| virtual int | local_g_space_points () const |
| virtual int | local_grid_points () const =0 |
| virtual int | local_offset () const =0 |
| virtual Complex * | output_buffer () const =0 |
| virtual bool | owns_stick (int, int) const |
| virtual void | prepare_forward_from_output () const =0 |
| virtual void | prepare_forward_from_output_on_slot (int) const |
Output-to-input copy on slot slot, the slot-aware prepare_forward_from_output(). | |
| virtual void | reduce_g_space (Complex *data, int number_of_elements) const =0 |
| virtual void | scatter_local_g_space (const Complex *local_g_space, Complex *full_g_space) const |
| The reverse: place this rank's reciprocal-space points into a full array. | |
| virtual int | slab_dimension_1 () const |
| virtual Complex * | slot_input_buffer (int) const |
| virtual Complex * | slot_output_buffer (int) const |
| virtual int | total_grid_points () const =0 |
Detailed Description
FFTGrid — Abstract interface for 3D FFT grids.
Provides a unified contract for real <-> reciprocal space transformations, shielding consumers from the details of memory distribution (serial vs. MPI).
Definition at line 16 of file fft_grid.hpp.
Constructor & Destructor Documentation
◆ ~FFTGrid()
|
virtualdefault |
Member Function Documentation
◆ assign_sticks()
|
inlinevirtual |
Assign reciprocal-space ownership from a weight per stick – the number of G-vectors on it inside the cutoff. Only a layout that distributes by stick has anything to do with it; everything else ignores it.
Reimplemented in q3::FFTGridSticks.
Definition at line 106 of file fft_grid.hpp.
Referenced by q3::PlanewaveBasis::generate(), and q3::PlanewaveBasis::initialize_kpoint_data().
◆ co_locates_mirrors()
|
inlinevirtual |
Whether a G-vector and its negative are always held by the same rank. True for a serial grid and for the stick layout; false for slabs, which is what forced the gamma-only path off under MPI.
Reimplemented in q3::FFTGridSticks.
Definition at line 113 of file fft_grid.hpp.
Referenced by q3::PlanewaveKohnShamSCFIterator::initialize_representation().
◆ concurrent_transform_slots()
|
inlinevirtual |
How many transforms this grid can have in flight at once.
The zero-copy buffer API above is a single set of scratch arrays, so two threads transforming through it at the same time would overwrite each other. A grid that can hand out independent scratch reports more than one slot here and honours the *_on_slot calls below; a grid that cannot leaves this at 1 and callers keep their band loops serial.
Slot 0 is always the buffers input_buffer() and output_buffer() return, so a caller that asks for one slot and a caller that never heard of slots drive exactly the same arrays through exactly the same plan. That is what keeps a one-thread run bit-identical to a build with no threading at all.
Reimplemented in q3::SerialFFTGrid.
Definition at line 235 of file fft_grid.hpp.
◆ execute_forward_on_buffers()
|
pure virtual |
Execute a forward FFT on the internal buffers (no copy).
Caller must have populated input_buffer() before calling. Result is available in output_buffer() after this call.
Implemented in q3::SerialFFTGrid, q3::FFTGridSticks, q3::gpu::CudaGPUFFTGrid, q3::gpu::HIPGPUFFTGrid, q3::gpu::MetalGPUFFTGrid, q3::gpu::SYCLGPUFFTGrid, and q3::SerialPocketFFTGrid.
Referenced by execute_forward_on_slot().
◆ execute_forward_on_slot()
|
inlinevirtual |
Forward transform on slot slot, the slot-aware execute_forward_on_buffers().
Reimplemented in q3::SerialFFTGrid.
Definition at line 261 of file fft_grid.hpp.
References execute_forward_on_buffers().
◆ execute_inverse_raw_on_buffers()
|
pure virtual |
Execute a raw inverse FFT on the internal buffers (no copy, no normalization).
Caller must have populated input_buffer() before calling. Result is available in output_buffer() after this call.
Implemented in q3::SerialFFTGrid, q3::FFTGridSticks, q3::gpu::CudaGPUFFTGrid, q3::gpu::HIPGPUFFTGrid, q3::gpu::MetalGPUFFTGrid, q3::gpu::SYCLGPUFFTGrid, and q3::SerialPocketFFTGrid.
Referenced by execute_inverse_raw_on_slot().
◆ execute_inverse_raw_on_slot()
|
inlinevirtual |
Inverse transform on slot slot, the slot-aware execute_inverse_raw_on_buffers().
Reimplemented in q3::SerialFFTGrid.
Definition at line 256 of file fft_grid.hpp.
References execute_inverse_raw_on_buffers().
◆ forward()
|
pure virtual |
Forward FFT: real-space -> reciprocal-space (unnormalized).
Implemented in q3::SerialFFTGrid, q3::FFTGridSticks, q3::gpu::CudaGPUFFTGrid, q3::gpu::HIPGPUFFTGrid, q3::gpu::MetalGPUFFTGrid, q3::gpu::SYCLGPUFFTGrid, and q3::SerialPocketFFTGrid.
Referenced by q3::compute_smooth_grid_potential_from_dense(), forward_batched(), q3::gpu::GPUFFTGrid::forward_transform(), q3::WavefunctionTransformer::r_to_g(), q3::ChargeDensityTransformer::rho_r_to_g(), and q3::PlanewaveDirectDiagonalizer::solve().
◆ forward_batched()
|
inlinevirtual |
Batched forward FFT: real-space -> reciprocal-space (unnormalized).
Transforms batch_size independent 3D grids packed contiguously: data[0 .. local_grid_points-1] = transform 0 data[local_grid_points .. 2*local_grid_points-1] = transform 1 ...
The default implementation loops over forward() for each transform.
Definition at line 319 of file fft_grid.hpp.
References forward(), and local_grid_points().
◆ g_vector_to_fft_grid_index()
|
pure virtual |
Map a G-vector (integer Miller indices) to FFT array index. Handles negative indices via wrapping.
Implemented in q3::SerialFFTGrid, q3::FFTGridSticks, q3::gpu::CudaGPUFFTGrid, q3::gpu::HIPGPUFFTGrid, q3::gpu::MetalGPUFFTGrid, q3::gpu::SYCLGPUFFTGrid, and q3::SerialPocketFFTGrid.
Referenced by q3::compute_g_to_fft_index_mapping(), q3::compute_smooth_grid_potential_from_dense(), q3::WavefunctionTransformer::g_to_r(), q3::WavefunctionTransformer::r_to_g(), q3::ChargeDensityTransformer::rho_g_to_r(), q3::ChargeDensityTransformer::rho_r_to_g(), and q3::PlanewaveDirectDiagonalizer::solve().
◆ gather_local_g_space()
|
inlinevirtual |
Copy this rank's reciprocal-space points out of a full, replicated G-space array laid out [i1][i2][i3], into the local G-space layout. The slab layout is a contiguous run at local_offset(); the stick layout is not, so consumers must go through this rather than a memcpy.
Reimplemented in q3::FFTGridSticks.
Definition at line 123 of file fft_grid.hpp.
References grid_dimension_2(), grid_dimension_3(), local_g_space_points(), and local_offset().
Referenced by q3::inverse_fft_smooth_potential().
◆ global_real_space_index()
|
inlinevirtual |
Where this rank's real-space point local_index sits in the whole grid, as the flat index i1·d2·d3 + i2·d3 + i3 that a serial grid stores it at.
Code that needs the position of a grid point – a multipole moment, a kernel evaluated at r – must ask this rather than add local_offset() planes: that is right for a serial grid and a slab along the first dimension, which is this default, and wrong for the stick layout, which holds planes along the third dimension and overrides it.
Reimplemented in q3::FFTGridSticks.
Definition at line 64 of file fft_grid.hpp.
References grid_dimension_2(), grid_dimension_3(), and local_offset().
Referenced by q3::MartynaTuckermanCorrectionCalculator::compute().
◆ grid_dimension_1()
|
pure virtual |
Grid size along the first dimension.
Implemented in q3::SerialFFTGrid, q3::FFTGridSticks, q3::gpu::CudaGPUFFTGrid, q3::gpu::HIPGPUFFTGrid, q3::gpu::MetalGPUFFTGrid, q3::gpu::SYCLGPUFFTGrid, and q3::SerialPocketFFTGrid.
Referenced by q3::MakovPayneCorrectionCalculator::compute(), q3::MartynaTuckermanCorrectionCalculator::compute(), q3::compute_g_to_fft_index_mapping(), q3::compute_smooth_grid_potential_from_dense(), q3::PlanewaveBasis::generate(), q3::PlanewaveKohnShamSCFIterator::log_representation_summary(), slab_dimension_1(), q3::PlanewaveDirectDiagonalizer::solve(), and q3::PlanewaveBasis::stick_weights_for_grid().
◆ grid_dimension_2()
|
pure virtual |
Grid size along the second dimension.
Implemented in q3::SerialFFTGrid, q3::FFTGridSticks, q3::gpu::CudaGPUFFTGrid, q3::gpu::HIPGPUFFTGrid, q3::gpu::MetalGPUFFTGrid, q3::gpu::SYCLGPUFFTGrid, and q3::SerialPocketFFTGrid.
Referenced by q3::MartynaTuckermanCorrectionCalculator::compute(), q3::compute_g_to_fft_index_mapping(), q3::compute_smooth_grid_potential_from_dense(), gather_local_g_space(), q3::PlanewaveBasis::generate(), global_real_space_index(), q3::PlanewaveKohnShamSCFIterator::log_representation_summary(), scatter_local_g_space(), q3::PlanewaveDirectDiagonalizer::solve(), and q3::PlanewaveBasis::stick_weights_for_grid().
◆ grid_dimension_3()
|
pure virtual |
Grid size along the third dimension.
Implemented in q3::SerialFFTGrid, q3::FFTGridSticks, q3::gpu::CudaGPUFFTGrid, q3::gpu::HIPGPUFFTGrid, q3::gpu::MetalGPUFFTGrid, q3::gpu::SYCLGPUFFTGrid, and q3::SerialPocketFFTGrid.
Referenced by q3::MartynaTuckermanCorrectionCalculator::compute(), q3::compute_g_to_fft_index_mapping(), q3::compute_smooth_grid_potential_from_dense(), gather_local_g_space(), q3::PlanewaveBasis::generate(), global_real_space_index(), q3::PlanewaveKohnShamSCFIterator::log_representation_summary(), scatter_local_g_space(), q3::PlanewaveDirectDiagonalizer::solve(), and q3::PlanewaveBasis::stick_weights_for_grid().
◆ init()
|
pure virtual |
Initialize with grid dimensions (dimension_1 x dimension_2 x dimension_3).
Implemented in q3::SerialFFTGrid, q3::FFTGridSticks, q3::gpu::CudaGPUFFTGrid, q3::gpu::HIPGPUFFTGrid, q3::gpu::MetalGPUFFTGrid, q3::gpu::SYCLGPUFFTGrid, and q3::SerialPocketFFTGrid.
Referenced by q3::GPUPlanewaveHamiltonianApplicator::GPUPlanewaveHamiltonianApplicator().
◆ initialize_batched_plans()
|
inlinevirtual |
Pre-create FFTW plans for batched transforms of a given batch size.
Must be called before forward_batched() or inverse_raw_batched() with the corresponding batch_size. Calling with a different batch_size replaces the existing batched plans.
The default implementation is a no-op (the fallback batched methods loop over single-transform calls, which need no separate plan).
Definition at line 292 of file fft_grid.hpp.
◆ initialized_batched_plan_size()
|
inlinevirtual |
Returns the batch_size for which batched plans are currently initialized, or 0 if no batched plans have been created.
Callers can use this to determine whether to zero-pad a smaller batch to the pre-initialized plan size (avoiding a plan recreation that would require a collective MPI call).
Definition at line 305 of file fft_grid.hpp.
◆ input_buffer()
|
pure virtual |
Access the FFT grid's internal input buffer for zero-copy transforms.
Callers scatter G-space data directly into this buffer, then call execute_inverse_raw_on_buffers() to transform in-place. This eliminates the memcpy overhead of inverse_raw() / forward().
The buffer has at least local_grid_points() elements of usable space.
Implemented in q3::SerialFFTGrid, q3::FFTGridSticks, q3::gpu::CudaGPUFFTGrid, q3::gpu::HIPGPUFFTGrid, q3::gpu::MetalGPUFFTGrid, q3::gpu::SYCLGPUFFTGrid, and q3::SerialPocketFFTGrid.
Referenced by slot_input_buffer().
◆ inverse()
|
pure virtual |
Inverse FFT: reciprocal-space -> real-space (includes 1/N normalization).
Implemented in q3::SerialFFTGrid, q3::FFTGridSticks, q3::gpu::CudaGPUFFTGrid, q3::gpu::HIPGPUFFTGrid, q3::gpu::MetalGPUFFTGrid, q3::gpu::SYCLGPUFFTGrid, and q3::SerialPocketFFTGrid.
Referenced by q3::WavefunctionTransformer::g_to_r(), q3::ChargeDensityTransformer::rho_g_to_r(), and q3::PlanewaveDirectDiagonalizer::solve().
◆ inverse_raw()
|
pure virtual |
Inverse FFT without 1/N normalization (raw FFTW backward).
Implemented in q3::SerialFFTGrid, q3::FFTGridSticks, q3::gpu::CudaGPUFFTGrid, q3::gpu::HIPGPUFFTGrid, q3::gpu::MetalGPUFFTGrid, q3::gpu::SYCLGPUFFTGrid, and q3::SerialPocketFFTGrid.
Referenced by q3::inverse_fft_smooth_potential(), inverse_raw_batched(), inverse_raw_on_slot(), and q3::gpu::GPUFFTGrid::inverse_transform().
◆ inverse_raw_batched()
|
inlinevirtual |
Batched inverse FFT without 1/N normalization (raw FFTW backward).
Transforms batch_size independent 3D grids packed contiguously (same layout as forward_batched).
The default implementation loops over inverse_raw() for each transform.
Definition at line 334 of file fft_grid.hpp.
References inverse_raw(), and local_grid_points().
◆ inverse_raw_on_slot()
|
inlinevirtual |
In-place inverse transform of a caller-owned array through slot slot, the slot-aware form of inverse_raw().
The array belongs to the caller, so two threads passing different arrays collide only over the grid's own scratch – which is what the slot separates.
Reimplemented in q3::SerialFFTGrid.
Definition at line 278 of file fft_grid.hpp.
References inverse_raw().
◆ local_g_space_points()
|
inlinevirtual |
Number of reciprocal-space points this rank holds.
Equal to local_grid_points() for every layout in which G-space and real space share a buffer. The stick decomposition holds G-space as whole sticks and real space as whole planes, so the two counts differ, and a caller sizing a G-space scatter must ask this rather than assume.
Reimplemented in q3::FFTGridSticks.
Definition at line 88 of file fft_grid.hpp.
References local_grid_points().
Referenced by q3::compute_smooth_grid_potential_from_dense(), q3::WavefunctionTransformer::g_to_r(), gather_local_g_space(), q3::inverse_fft_smooth_potential(), q3::WavefunctionTransformer::r_to_g(), q3::ChargeDensityTransformer::rho_g_to_r(), q3::ChargeDensityTransformer::rho_r_to_g(), and scatter_local_g_space().
◆ local_grid_points()
|
pure virtual |
Number of real-space grid points stored on the local rank.
Implemented in q3::SerialFFTGrid, q3::FFTGridSticks, q3::gpu::CudaGPUFFTGrid, q3::gpu::HIPGPUFFTGrid, q3::gpu::MetalGPUFFTGrid, q3::gpu::SYCLGPUFFTGrid, and q3::SerialPocketFFTGrid.
Referenced by q3::PlanewaveChargeDensityAccumulator::accumulate(), q3::GPUPlanewaveHamiltonianApplicator::apply_batch(), q3::GPUPlanewaveHamiltonianApplicator::apply_batch_single_precision(), q3::PlanewaveEffectivePotentialCalculator::build_exchange_correlation_density(), q3::NormConservingPlanewaveEffectivePotentialCalculator::build_exchange_correlation_density(), q3::MartynaTuckermanCorrectionCalculator::compute(), q3::PlanewaveEffectivePotentialCalculator::compute(), q3::PlanewaveKohnShamSCFIterator::compute_delta_escf_correction(), q3::PlanewaveKohnShamSCFIterator::compute_double_counting_correction(), q3::compute_smooth_grid_potential_from_dense(), q3::GradientCorrectedExchangeCorrelationPotentialCalculator::evaluate_spin_polarized(), q3::GradientCorrectedExchangeCorrelationPotentialCalculator::evaluate_unpolarized(), forward_batched(), q3::WavefunctionTransformer::g_to_r(), q3::inverse_fft_smooth_potential(), inverse_raw_batched(), q3::PlanewaveKohnShamSCFIterator::loaded_charge_density_fits_grid(), local_g_space_points(), q3::WavefunctionTransformer::r_to_g(), q3::ChargeDensityTransformer::rho_g_to_r(), q3::ChargeDensityTransformer::rho_r_to_g(), q3::GPUPlanewaveHamiltonianApplicator::update_potential(), q3::SerialPlanewaveHamiltonianApplicator::update_potential(), and q3::PlanewaveKohnShamSCFIterator::warn_if_total_charge_deviates().
◆ local_offset()
|
pure virtual |
Offset into the global grid for the local segment (e.g., start of slab).
Implemented in q3::SerialFFTGrid, q3::FFTGridSticks, q3::gpu::CudaGPUFFTGrid, q3::gpu::HIPGPUFFTGrid, q3::gpu::MetalGPUFFTGrid, q3::gpu::SYCLGPUFFTGrid, and q3::SerialPocketFFTGrid.
Referenced by gather_local_g_space(), global_real_space_index(), and scatter_local_g_space().
◆ output_buffer()
|
pure virtual |
Access the FFT grid's internal output buffer for zero-copy transforms.
After execute_inverse_raw_on_buffers(), real-space data is here. After execute_forward_on_buffers(), G-space data is here.
For in-place plans (MPI FFT), this returns the same pointer as input_buffer(). For out-of-place plans (Serial FFT), this is a separate buffer.
Implemented in q3::SerialFFTGrid, q3::FFTGridSticks, q3::gpu::CudaGPUFFTGrid, q3::gpu::HIPGPUFFTGrid, q3::gpu::MetalGPUFFTGrid, q3::gpu::SYCLGPUFFTGrid, and q3::SerialPocketFFTGrid.
Referenced by slot_output_buffer().
◆ owns_stick()
|
inlinevirtual |
Whether this rank holds the G-vectors sharing the first two Miller indices. True everywhere for a layout that does not distribute G-space by stick; the plane-wave selector asks this to decide what to keep.
Reimplemented in q3::FFTGridSticks.
Definition at line 97 of file fft_grid.hpp.
◆ prepare_forward_from_output()
|
pure virtual |
Prepare the input buffer for a forward transform after modifying the output buffer.
For out-of-place plans (Serial FFT), this copies output_buffer → input_buffer. For in-place plans (MPI FFT), this is a no-op (same buffer).
Call this between the real-space multiply and execute_forward_on_buffers().
Implemented in q3::SerialFFTGrid, q3::FFTGridSticks, q3::gpu::CudaGPUFFTGrid, q3::gpu::HIPGPUFFTGrid, q3::gpu::MetalGPUFFTGrid, q3::gpu::SYCLGPUFFTGrid, and q3::SerialPocketFFTGrid.
Referenced by prepare_forward_from_output_on_slot().
◆ prepare_forward_from_output_on_slot()
|
inlinevirtual |
Output-to-input copy on slot slot, the slot-aware prepare_forward_from_output().
Reimplemented in q3::SerialFFTGrid.
Definition at line 266 of file fft_grid.hpp.
References prepare_forward_from_output().
◆ reduce_g_space()
|
pure virtual |
Reduce G-space data across the pool to make it redundant on all ranks.
Serial: no-op. MPI: MPI_Allreduce(MPI_IN_PLACE, ..., MPI_SUM, pool_comm).
Implemented in q3::SerialFFTGrid, q3::SerialPocketFFTGrid, q3::FFTGridSticks, q3::gpu::CudaGPUFFTGrid, q3::gpu::HIPGPUFFTGrid, q3::gpu::MetalGPUFFTGrid, and q3::gpu::SYCLGPUFFTGrid.
Referenced by q3::ChargeDensityTransformer::rho_r_to_g().
◆ scatter_local_g_space()
|
inlinevirtual |
The reverse: place this rank's reciprocal-space points into a full array.
Reimplemented in q3::FFTGridSticks.
Definition at line 133 of file fft_grid.hpp.
References grid_dimension_2(), grid_dimension_3(), local_g_space_points(), and local_offset().
◆ slab_dimension_1()
|
inlinevirtual |
Number of first-dimension planes owned by this rank for G-vector partitioning.
In serial mode this equals grid_dimension_1(). In MPI mode this returns the slab size (local_n1 from FFTW's decomposition), which may differ from local_grid_points() / (dim2*dim3) when the FFT operates on the full grid (Allreduce mode).
Reimplemented in q3::FFTGridSticks.
Definition at line 76 of file fft_grid.hpp.
References grid_dimension_1().
◆ slot_input_buffer()
|
inlinevirtual |
The input buffer of transform slot slot, the slot-aware form of input_buffer().
Reimplemented in q3::SerialFFTGrid.
Definition at line 243 of file fft_grid.hpp.
References input_buffer().
◆ slot_output_buffer()
|
inlinevirtual |
The output buffer of transform slot slot, the slot-aware form of output_buffer().
Reimplemented in q3::SerialFFTGrid.
Definition at line 251 of file fft_grid.hpp.
References output_buffer().
◆ total_grid_points()
|
pure virtual |
Total number of real-space grid points across all processes.
Implemented in q3::SerialFFTGrid, q3::FFTGridSticks, q3::gpu::CudaGPUFFTGrid, q3::gpu::HIPGPUFFTGrid, q3::gpu::MetalGPUFFTGrid, q3::gpu::SYCLGPUFFTGrid, and q3::SerialPocketFFTGrid.
Referenced by q3::PlanewaveChargeDensity::PlanewaveChargeDensity(), q3::PlanewaveEffectivePotential::PlanewaveEffectivePotential(), q3::PlanewaveChargeDensityAccumulator::accumulate(), q3::PlanewaveEffectivePotentialCalculator::compute(), q3::PlanewaveKohnShamSCFIterator::compute_delta_escf_correction(), q3::PlanewaveKohnShamSCFIterator::compute_double_counting_correction(), q3::compute_smooth_grid_potential_from_dense(), q3::gpu::GPUFFTGrid::forward_single_batch(), q3::gpu::GPUFFTGrid::forward_transform_batch(), q3::PlanewaveChargeDensity::get_total_charge(), q3::PlanewaveChargeDensity::grid_size(), q3::PlanewaveEffectivePotential::grid_size(), q3::PlanewaveEffectivePotential::initialize_kinetic_potential(), q3::PlanewavePseudopotentialKohnShamSCFIterator::initialize_single_particle_states(), q3::gpu::GPUFFTGrid::inverse_raw_single_batch(), q3::gpu::GPUFFTGrid::inverse_transform_batch(), q3::PlanewaveKohnShamSCFIterator::preload_charge_density(), q3::PlanewaveKohnShamSCFIterator::report_convergence_details(), q3::PlanewaveChargeDensity::reset(), q3::ChargeDensityTransformer::rho_g_to_r(), q3::ChargeDensityTransformer::rho_r_to_g(), q3::PlanewaveKohnShamSCFIterator::scale_loaded_charge_density_to_electron_count(), q3::PlanewaveDirectDiagonalizer::solve(), q3::PlanewaveChargeDensity::to_reciprocal_space(), q3::PlanewaveEffectivePotential::to_reciprocal_space(), q3::GPUPlanewaveHamiltonianApplicator::update_potential(), q3::SerialPlanewaveHamiltonianApplicator::update_potential(), and q3::PlanewaveKohnShamSCFIterator::warn_if_total_charge_deviates().
The documentation for this class was generated from the following file:
- src/layer_3_representation/basis/planewave/internal/fft/fft_grid.hpp
