#include <init.hpp>
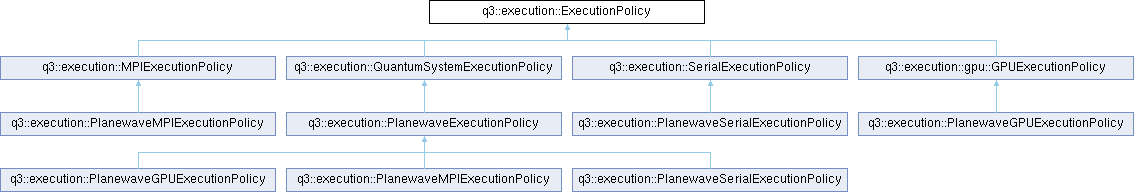
 Inheritance diagram for q3::execution::ExecutionPolicy:
Public Types | |
| using | ComplexValue = Complex |
Public Member Functions | |
| virtual | ~ExecutionPolicy ()=default |
| virtual void | add_scaled_vector (int number_of_elements, ComplexValue scaling_factor, const ComplexValue *vector_x, ComplexValue *vector_y) const =0 |
| virtual void | allgather_across_bands (ComplexValue *, const int *, const int *) const |
| virtual void | allgather_within_group (const Real *local_data, int local_count, Real *full_data, int total_count) const =0 |
| virtual int | band_distribution_rank_index () const |
| virtual int | band_distribution_size () const |
| virtual void | broadcast_across_bands (ComplexValue *, int) const |
| virtual void | broadcast_across_bands (int *, int) const |
| Integer overload, for the counts that decide collective sizes. | |
| virtual void | broadcast_across_bands (Real *, int) const |
| Real overload, for eigenvalues – the numbers convergence decisions are made from. | |
| virtual void | broadcast_from_group_root (ComplexValue *, int) const |
| virtual void | broadcast_from_group_root (Real *, int) const |
| virtual ComplexValue | dot_product (int number_of_elements, const ComplexValue *vector_x, const ComplexValue *vector_y) const =0 |
| virtual int | global_number_of_elements (int local_number_of_elements) const =0 |
| virtual int | group_rank_index () const =0 |
| virtual int | group_size () const =0 |
| virtual bool | is_root () const =0 |
| virtual Real | norm (int number_of_elements, const ComplexValue *vector_x) const =0 |
| virtual int | number_of_processes () const =0 |
| virtual void | reduce_across_bands (Real *, int) const |
| virtual void | reduce_group_distributed_result (ComplexValue *, int) const |
| virtual void | reduce_within_group (ComplexValue *data, int number_of_elements) const =0 |
| virtual void | reduce_within_group (Real *data, int number_of_elements) const =0 |
|
virtualdefault |
|
pure virtual |
Scaled vector addition in-place: vector_y += scaling_factor * vector_x.
| number_of_elements | Length of both vectors. |
| scaling_factor | Complex scaling coefficient. |
| vector_x | Source vector. |
| vector_y | Destination vector (modified in-place). |
Implemented in q3::execution::gpu::GPUExecutionPolicy, q3::execution::MPIExecutionPolicy, q3::execution::SerialExecutionPolicy, and q3::execution::PlanewaveGPUExecutionPolicy.
|
inlinevirtual |
Complete an array whose local band block is already written in place.
Each rank has filled its own contiguous block of data; afterwards every rank holds all blocks. counts and displacements are in complex elements and indexed by band-distribution rank, so a caller hands over the same partition it used to divide the work.
The in-place contract is deliberate. Gathering from a sub-range of the destination into that same destination aliases the send and receive buffers, which MPI forbids; requiring the block to be in place already is what lets the implementation say so with MPI_IN_PLACE instead. No-op when bands are not distributed – the one block is the whole array.
Reimplemented in q3::execution::MPIExecutionPolicy.
Definition at line 265 of file init.hpp.
Referenced by q3::SerialPlanewaveHamiltonianApplicator::apply_batch(), q3::SerialPlanewaveSubspaceManager::build_correction_vectors(), and q3::SerialPlanewaveSubspaceManager::multiply_basis_by_coefficients_across_bands().
|
pure virtual |
Allgather rank-local slab data into a full-size buffer on every rank.
Gathers each group rank's contiguous local slice into a contiguous full array on every rank (concatenated in rank order). No-op when group_size == 1.
| local_data | Rank-local slab data. |
| local_count | Number of real elements in the local slab. |
| full_data | Output: full-grid data (all slabs concatenated). |
| total_count | Total number of real elements across all ranks. |
Implemented in q3::execution::gpu::GPUExecutionPolicy, q3::execution::MPIExecutionPolicy, and q3::execution::SerialExecutionPolicy.
Referenced by q3::SerialPlanewaveHamiltonianApplicator::update_potential().
|
inlinevirtual |
This rank's index within the band split. 0 when bands are not distributed.
Reimplemented in q3::execution::MPIExecutionPolicy.
Definition at line 247 of file init.hpp.
Referenced by q3::SerialPlanewaveHamiltonianApplicator::apply_batch(), q3::SerialPlanewaveSubspaceManager::build_correction_vectors(), and q3::SerialPlanewaveSubspaceManager::multiply_basis_by_coefficients_across_bands().
|
inlinevirtual |
── Band distribution ─────────────────────────────────────────────────────
A second, mutually exclusive way to divide work within a k-point pool. Where group distribution splits the reciprocal-space coefficients of every band across ranks, band distribution splits the bands and leaves each rank holding complete coefficient vectors.
The two cannot both be active: a rank either owns all of G for some bands or some of G for all bands. When bands are distributed, group distribution is switched off (group_size() reports 1), so every reduce_within_group() correctly becomes a no-op – the coefficients each rank contracts over are whole, not partial. What replaces those reductions is an allgather over the band axis, once per batch, rather than a reduction per inner product.
Every method below is defaulted to the replicated, single-rank answer, so a policy that does not distribute bands inherits correct behaviour. Number of ranks sharing the band split. 1 when bands are not distributed.
Reimplemented in q3::execution::MPIExecutionPolicy.
Definition at line 240 of file init.hpp.
Referenced by q3::SerialPlanewaveHamiltonianApplicator::apply_batch(), q3::SerialPlanewaveSubspaceManager::build_correction_vectors(), q3::PlanewaveKohnShamSCFIterator::log_representation_summary(), and q3::SerialPlanewaveSubspaceManager::multiply_basis_by_coefficients_across_bands().
|
inlinevirtual |
Republish an array from the first rank of the band split to the rest.
This exists because "every rank recomputes the same thing from the same data, so every rank agrees" is not true in practice. Vendor BLAS picks its blocking and summation order from what the machine looks like at the time, so two processes running identical arithmetic on identical inputs can differ in the last bits – measured here at a relative 1e-15 on the first expansion. Davidson then amplifies that: orthogonalisation rejects candidates on a threshold, so a last-bit difference changes how many vectors a rank accepts, the ranks stop agreeing on the size of the next batch, and the collective that follows fails outright.
Broadcasting the redundantly computed result makes one rank's arithmetic authoritative, which restores exactly the agreement the design assumed. No-op when bands are not distributed.
Reimplemented in q3::execution::MPIExecutionPolicy.
Definition at line 293 of file init.hpp.
Referenced by q3::SerialPlanewaveSubspaceManager::collapse_subspace(), and q3::PlanewaveDavidsonDiagonalizer::solve().
|
inlinevirtual |
Integer overload, for the counts that decide collective sizes.
Reimplemented in q3::execution::MPIExecutionPolicy.
|
inlinevirtual |
Real overload, for eigenvalues – the numbers convergence decisions are made from.
Reimplemented in q3::execution::MPIExecutionPolicy.
|
inlinevirtual |
Broadcast complex data from the group root (rank 0) to all ranks in the group.
Used to avoid replicated LAPACK computation: rank 0 computes, then broadcasts the result. No-op when group_size == 1.
| data | In-out array of complex values. |
| number_of_elements | Number of complex elements to broadcast. |
Reimplemented in q3::execution::MPIExecutionPolicy.
Definition at line 310 of file init.hpp.
Referenced by q3::GPUPlanewaveSubspaceManager::diagonalize_subspace(), and q3::SerialPlanewaveSubspaceManager::diagonalize_subspace().
|
inlinevirtual |
Broadcast real data from the group root (rank 0) to all ranks in the group.
| data | In-out array of real values. |
| number_of_elements | Number of real elements to broadcast. |
Reimplemented in q3::execution::MPIExecutionPolicy.
|
pure virtual |
Compute the inner product x† · y, optionally reduced across the process group.
| number_of_elements | Length of both vectors. |
| vector_x | Left operand (conjugated). |
| vector_y | Right operand. |
Implemented in q3::execution::gpu::GPUExecutionPolicy, q3::execution::MPIExecutionPolicy, q3::execution::SerialExecutionPolicy, and q3::execution::PlanewaveGPUExecutionPolicy.
|
pure virtual |
Sum a rank-local element count across the process group.
Distributed vector algorithms use this to distinguish the local slab length from the dimension of the complete vector space.
Implemented in q3::execution::gpu::GPUExecutionPolicy, q3::execution::MPIExecutionPolicy, and q3::execution::SerialExecutionPolicy.
Referenced by q3::PlanewaveDavidsonDiagonalizer::solve().
|
pure virtual |
Index of this process within its process group.
0 in serial mode. NOT necessarily 0 when group_size() == 1: a group whose data distribution was disabled at run time (see MPIExecutionPolicy::disable_group_distribution) reports group_size() == 1 while keeping its pool-local rank index, because the pool identity is still needed. Use group_size() <= 1 to ask "is my data replicated"; use group_rank_index() == 0 only to pick one representative per pool.
Implemented in q3::execution::gpu::GPUExecutionPolicy, q3::execution::MPIExecutionPolicy, and q3::execution::SerialExecutionPolicy.
Referenced by q3::execution::QuantumSystemExecutionPolicy::band_rank_index(), q3::GPUPlanewaveSubspaceManager::diagonalize_subspace(), and q3::SerialPlanewaveSubspaceManager::diagonalize_subspace().
|
pure virtual |
Number of processes in this process group. Always 1 in serial mode or when each group contains a single process.
Implemented in q3::execution::gpu::GPUExecutionPolicy, q3::execution::MPIExecutionPolicy, and q3::execution::SerialExecutionPolicy.
Referenced by q3::execution::QuantumSystemExecutionPolicy::band_size(), q3::SubspaceDiagonalizerFactory::create(), q3::GPUPlanewaveSubspaceManager::diagonalize_subspace(), q3::SerialPlanewaveSubspaceManager::diagonalize_subspace(), and q3::SerialPlanewaveHamiltonianApplicator::update_potential().
|
pure virtual |
Check if this process is the root process (rank 0 in the world communicator).
Used by entry points to ensure only one process writes output files or logs non-essential information.
Implemented in q3::execution::gpu::GPUExecutionPolicy, q3::execution::MPIExecutionPolicy, and q3::execution::SerialExecutionPolicy.
Referenced by q3::export_and_record_mean_field_under_topology(), q3::PlanewaveKohnShamSCFIterator::warn_if_total_charge_deviates(), and q3::PlanewavePseudopotentialKohnShamSCFIterator::write_checkpoints().
|
pure virtual |
Compute the Euclidean norm, optionally reduced across the process group.
| number_of_elements | Length of the vector. |
| vector_x | Input vector. |
Implemented in q3::execution::gpu::GPUExecutionPolicy, q3::execution::MPIExecutionPolicy, q3::execution::SerialExecutionPolicy, and q3::execution::PlanewaveGPUExecutionPolicy.
|
pure virtual |
Number of processes in the complete execution topology.
Implemented in q3::execution::gpu::GPUExecutionPolicy, q3::execution::MPIExecutionPolicy, and q3::execution::SerialExecutionPolicy.
Referenced by q3::create_kohn_sham_iterator(), q3::execution::PlanewaveExecutionPolicy::execution_record(), and q3::PlanewaveKohnShamSCFIterator::log_representation_summary().
|
inlinevirtual |
Sum an array across the band split, so that a quantity accumulated from disjoint band ranges (the charge density above all) becomes whole. No-op when bands are not distributed.
Reimplemented in q3::execution::MPIExecutionPolicy.
|
inlinevirtual |
Reduce group-distributed partial results across the process group.
Used when different ranks compute disjoint contributions to the same output array. Unlike reduce_within_group (which is a no-op when the input vectors are replicated), this always performs the reduction when group_size > 1. No-op in serial.
| data | In-out array of complex values. |
| number_of_elements | Number of complex elements to reduce. |
Reimplemented in q3::execution::MPIExecutionPolicy.
Definition at line 215 of file init.hpp.
Referenced by q3::PlanewavePseudopotentialKohnShamSCFIterator::initialize_single_particle_states().
|
pure virtual |
Allreduce an array of complex values within the process group.
Used after ZGEMM-based inner products over the distributed vector dimension (e.g., subspace matrices, orthogonalization overlaps) when coefficient vectors are distributed across group ranks. No-op when group_size == 1.
| data | In-out array of complex values. |
| number_of_elements | Number of complex elements to reduce. |
Implemented in q3::execution::gpu::GPUExecutionPolicy, q3::execution::SerialExecutionPolicy, and q3::execution::MPIExecutionPolicy.
Referenced by q3::PlanewavePseudopotentialKohnShamSCFIterator::accumulate_hubbard_occupation_and_potential(), q3::UltrasoftPlanewavePseudopotentialKohnShamSCFIterator::accumulate_projector_overlaps(), q3::UltrasoftPseudopotentialOverlapOperator::apply(), q3::UltrasoftPseudopotentialOverlapOperator::apply_batch(), q3::HubbardStressTensorCalculator::compute(), q3::HubbardForceCalculator::compute(), q3::NonlocalPseudopotentialForceCalculator::compute(), q3::GPUPlanewaveSubspaceManager::orthogonalize_batch(), q3::SerialPlanewaveSubspaceManager::orthogonalize_batch(), q3::PlanewavePseudopotentialKohnShamSCFIterator::setup_hubbard(), q3::PlanewaveDirectDiagonalizer::solve(), q3::GPUPlanewaveSubspaceManager::update_subspace_matrices(), q3::SerialPlanewaveSubspaceManager::update_subspace_matrices(), and q3::PlanewaveKohnShamSCFIterator::warn_if_total_charge_deviates().
|
pure virtual |
Allreduce an array of real values within the process group.
Same as the complex variant but for real-valued arrays.
| data | In-out array of real values. |
| number_of_elements | Number of real elements to reduce. |
Implemented in q3::execution::gpu::GPUExecutionPolicy, q3::execution::SerialExecutionPolicy, and q3::execution::MPIExecutionPolicy.
 1.9.8