#include <mpi.hpp>
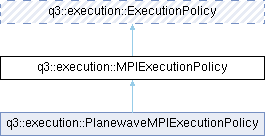
 Inheritance diagram for q3::execution::MPIExecutionPolicy:
Public Member Functions | |
| MPIExecutionPolicy () | |
| MPIExecutionPolicy (const MPIExecutionPolicy &)=delete | |
| ~MPIExecutionPolicy () override | |
| void | add_scaled_vector (int number_of_elements, ComplexValue scaling_factor, const ComplexValue *vector_x, ComplexValue *vector_y) const override |
| void | allgather_across_bands (ComplexValue *data, const int *counts, const int *displacements) const override |
| void | allgather_within_group (const Real *local_data, int local_count, Real *full_data, int) const override |
| int | band_distribution_rank_index () const override |
| int | band_distribution_size () const override |
| void | broadcast_across_bands (ComplexValue *data, int number_of_elements) const override |
| void | broadcast_across_bands (int *data, int number_of_elements) const override |
| Integer overload, for the counts that decide collective sizes. | |
| void | broadcast_across_bands (Real *data, int number_of_elements) const override |
| Real overload, for eigenvalues – the numbers convergence decisions are made from. | |
| void | broadcast_from_group_root (ComplexValue *data, int number_of_elements) const override |
| void | broadcast_from_group_root (Real *data, int number_of_elements) const override |
| void | configure_group_topology (int number_of_groups) |
| void | disable_group_distribution () |
| ComplexValue | dot_product (int number_of_elements, const ComplexValue *vector_x, const ComplexValue *vector_y) const override |
| void | enable_band_distribution () |
| MPI_Comm | get_group_communicator () const |
| MPI_Comm | get_world_communicator () const |
| int | global_number_of_elements (int local_number_of_elements) const override |
| int | group_index () const |
| int | group_rank_index () const override |
| int | group_size () const override |
| bool | is_root () const override |
| Real | norm (int number_of_elements, const ComplexValue *vector_x) const override |
| int | number_of_processes () const override |
| MPIExecutionPolicy & | operator= (const MPIExecutionPolicy &)=delete |
| void | reduce_across_bands (Real *data, int number_of_elements) const override |
| void | reduce_group_distributed_result (ComplexValue *data, int number_of_elements) const override |
| void | reduce_within_group (ComplexValue *data, int number_of_elements) const override |
| void | reduce_within_group (Real *data, int number_of_elements) const override |
| int | world_rank_index () const |
| int | world_size () const |
| Public Member Functions inherited from q3::execution::ExecutionPolicy | |
| virtual | ~ExecutionPolicy ()=default |
Protected Attributes | |
| int | band_distribution_rank_index_ = 0 |
| int | band_distribution_size_ = 1 |
| MPI_Comm | group_communicator_ = MPI_COMM_NULL |
| int | group_index_ = 0 |
| int | group_rank_index_ = 0 |
| int | group_size_ = 1 |
Additional Inherited Members | |
| Public Types inherited from q3::execution::ExecutionPolicy | |
| using | ComplexValue = Complex |
|
inline |
Initialize MPI (if not already initialized) and set up communicators.
Uses MPI_Init(nullptr, nullptr) — valid since MPI-2. If MPI is already initialized (e.g., by a test harness), initialization is skipped and MPI_Finalize will not be called on destruction.
Default: group communicator is the full world until configure_group_topology() is called. Future multi-rank group parallelism will split this into process groups.
Definition at line 53 of file mpi.hpp.
References group_communicator_, group_index_, group_rank_index_, and group_size_.
|
inlineoverride |
Free split communicators and finalize MPI (if we initialized it).
Guards every MPI call with MPI_Finalized() so that this destructor is safe to invoke even if MPI has already been finalized (e.g., when the policy object is owned by a unique_ptr that outlives global teardown).
The barrier before MPI_Finalize() ensures that all ranks have finished their pending work before any rank finalizes. Without it, on macOS with –oversubscribe, rank 0 can reach MPI_Finalize() while non-root ranks are still processing trailing work (e.g., logging), causing SIGSEGV in OpenMPI's shared-memory cleanup.
Teardown is skipped entirely while an exception is in flight, because every step of it is collective – MPI_Comm_free and MPI_Finalize no less than the barrier – and each one only completes once every rank calls it. A rank unwinding alone has no reason to believe its peers are unwinding too: they are still inside a physics collective, and will not arrive. Running teardown anyway is what turns a rank-local error – an unreadable file, a failed allocation, anything one rank sees and the others do not – into a job that hangs instead of failing, with the message still unsent because the handler that prints it is never reached. Doing nothing here leaves MPI live for that handler, which reports the error and calls MPI_Abort to take the blocked peers down with it (see main_mpi.cpp). Communicators leak, which costs nothing in a process that is about to die and cannot be avoided regardless: there is no non-collective way to release them.
A collective failure – every rank throwing the same thing, such as the shared-pool refusal in the Kohn-Sham factory – also lands here, on every rank, and takes the same path. That path is safe for it too: each rank reports before it aborts.
Definition at line 192 of file mpi.hpp.
References group_communicator_.
|
delete |
|
inlineoverridevirtual |
Scaled vector addition: purely local, no communication.
Implements q3::execution::ExecutionPolicy.
Definition at line 237 of file mpi.hpp.
References q3::execution::SerialExecutionPolicy::add_scaled_vector().
|
inlineoverridevirtual |
Complete an array whose local band block is already written in place.
Each rank has filled its own contiguous block of data; afterwards every rank holds all blocks. counts and displacements are in complex elements and indexed by band-distribution rank, so a caller hands over the same partition it used to divide the work.
The in-place contract is deliberate. Gathering from a sub-range of the destination into that same destination aliases the send and receive buffers, which MPI forbids; requiring the block to be in place already is what lets the implementation say so with MPI_IN_PLACE instead. No-op when bands are not distributed – the one block is the whole array.
Counts arrive in complex elements because that is the unit bands are partitioned in; the complex datatype makes that the wire unit too, so there is no doubling here. MPI_IN_PLACE says the local block is already at its own displacement, which is the contract this method documents.
The send arguments are ignored under MPI_IN_PLACE, but they remain arguments an implementation may check, so they name the same datatype rather than a null one.
Reimplemented from q3::execution::ExecutionPolicy.
Definition at line 384 of file mpi.hpp.
References band_distribution_size_, q3::execution::complex_datatype(), and group_communicator_.
|
inlineoverridevirtual |
Allgather rank-local slab data into a full-size buffer on every rank.
Gathers each group rank's contiguous local slice into a contiguous full array on every rank (concatenated in rank order). No-op when group_size == 1.
| local_data | Rank-local slab data. |
| local_count | Number of real elements in the local slab. |
| full_data | Output: full-grid data (all slabs concatenated). |
| total_count | Total number of real elements across all ranks. |
Implements q3::execution::ExecutionPolicy.
Definition at line 317 of file mpi.hpp.
References group_communicator_, and group_size_.
|
inlineoverridevirtual |
This rank's index within the band split. 0 when bands are not distributed.
Reimplemented from q3::execution::ExecutionPolicy.
Definition at line 380 of file mpi.hpp.
References band_distribution_rank_index_.
|
inlineoverridevirtual |
── Band distribution ─────────────────────────────────────────────────────
A second, mutually exclusive way to divide work within a k-point pool. Where group distribution splits the reciprocal-space coefficients of every band across ranks, band distribution splits the bands and leaves each rank holding complete coefficient vectors.
The two cannot both be active: a rank either owns all of G for some bands or some of G for all bands. When bands are distributed, group distribution is switched off (group_size() reports 1), so every reduce_within_group() correctly becomes a no-op – the coefficients each rank contracts over are whole, not partial. What replaces those reductions is an allgather over the band axis, once per batch, rather than a reduction per inner product.
Every method below is defaulted to the replicated, single-rank answer, so a policy that does not distribute bands inherits correct behaviour. Number of ranks sharing the band split. 1 when bands are not distributed.
Reimplemented from q3::execution::ExecutionPolicy.
Definition at line 376 of file mpi.hpp.
References band_distribution_size_.
|
inlineoverridevirtual |
Republish an array from the first rank of the band split to the rest.
This exists because "every rank recomputes the same thing from the same data, so every rank agrees" is not true in practice. Vendor BLAS picks its blocking and summation order from what the machine looks like at the time, so two processes running identical arithmetic on identical inputs can differ in the last bits – measured here at a relative 1e-15 on the first expansion. Davidson then amplifies that: orthogonalisation rejects candidates on a threshold, so a last-bit difference changes how many vectors a rank accepts, the ranks stop agreeing on the size of the next batch, and the collective that follows fails outright.
Broadcasting the redundantly computed result makes one rank's arithmetic authoritative, which restores exactly the agreement the design assumed. No-op when bands are not distributed.
Reimplemented from q3::execution::ExecutionPolicy.
Definition at line 410 of file mpi.hpp.
References band_distribution_size_, q3::execution::complex_datatype(), and group_communicator_.
|
inlineoverridevirtual |
Integer overload, for the counts that decide collective sizes.
Reimplemented from q3::execution::ExecutionPolicy.
Definition at line 416 of file mpi.hpp.
References band_distribution_size_, and group_communicator_.
|
inlineoverridevirtual |
Real overload, for eigenvalues – the numbers convergence decisions are made from.
Reimplemented from q3::execution::ExecutionPolicy.
Definition at line 422 of file mpi.hpp.
References band_distribution_size_, and group_communicator_.
|
inlineoverridevirtual |
Broadcast complex data from the group root (rank 0) to all ranks in the group.
Used to avoid replicated LAPACK computation: rank 0 computes, then broadcasts the result. No-op when group_size == 1.
| data | In-out array of complex values. |
| number_of_elements | Number of complex elements to broadcast. |
Reimplemented from q3::execution::ExecutionPolicy.
Definition at line 362 of file mpi.hpp.
References q3::execution::complex_datatype(), group_communicator_, and group_size_.
|
inlineoverridevirtual |
Broadcast real data from the group root (rank 0) to all ranks in the group.
| data | In-out array of real values. |
| number_of_elements | Number of real elements to broadcast. |
Reimplemented from q3::execution::ExecutionPolicy.
Definition at line 369 of file mpi.hpp.
References group_communicator_, and group_size_.
|
inline |
Configure the process group topology by splitting the world communicator.
Processes are divided into 'number_of_groups' equal groups of 'world_size / number_of_groups' consecutive ranks. Collective vector operations subsequently reduce over the group communicator.
| number_of_groups | Number of independent process groups. |
Split world into groups based on their index. All ranks in the same group share the same color.
Definition at line 99 of file mpi.hpp.
References group_communicator_, group_index_, group_rank_index_, group_size(), and group_size_.
Referenced by q3::execution::PlanewaveMPIExecutionPolicy::configure_topology().
|
inline |
Disable data distribution within the process group.
Resets group_size to 1 so that all group-collective reductions (dot_product, reduce_within_group, and the pool-level reductions built on them) become no-ops. Used by higher layers when their data distribution degenerates and they fall back to replicated data — see PlanewaveExecutionPolicy::disable_band_distribution().
The group communicator and configured group index remain intact. Only the active reduction size changes, so higher layers retain the correct k-point-pool identity while working with replicated coefficient data.
Note what this leaves behind: group_size() becomes 1 while group_rank_index() keeps its pool-local value, so on ranks other than the pool root the two disagree about whether "this is a group of one". Code choosing which rank performs a redundant computation must branch on group_size() <= 1, not on group_rank_index() == 0.
Definition at line 141 of file mpi.hpp.
References group_size_.
Referenced by q3::execution::PlanewaveMPIExecutionPolicy::disable_band_distribution(), and enable_band_distribution().
|
inlineoverridevirtual |
Dot product of two (possibly distributed) coefficient vectors.
With data distribution, each rank holds a slice of the coefficients. The local dot product is partial and must be summed across group ranks via MPI_Allreduce.
Implements q3::execution::ExecutionPolicy.
Definition at line 223 of file mpi.hpp.
References q3::execution::SerialExecutionPolicy::dot_product(), group_communicator_, group_size_, and q3::execution::sum_complex_in_place().
Referenced by norm().
|
inline |
Switch this pool from distributing reciprocal space to distributing bands.
Records how many ranks share the pool, then disables group distribution so that every rank keeps whole coefficient vectors and each reduce_within_group becomes a no-op. The group communicator is deliberately left intact: it is what the band allgather and the density reduction run over.
Definition at line 153 of file mpi.hpp.
References band_distribution_rank_index_, band_distribution_size_, disable_group_distribution(), group_rank_index_, and group_size_.
|
inline |
Definition at line 358 of file mpi.hpp.
References group_communicator_.
Referenced by q3::execution::PlanewaveMPIExecutionPolicy::create_fft_grid(), q3::execution::PlanewaveMPIExecutionPolicy::reduce_band_group_scalar_min(), q3::execution::PlanewaveMPIExecutionPolicy::reduce_within_pool_scalar(), and q3::execution::PlanewaveMPIExecutionPolicy::reduce_within_pool_vector().
|
inline |
|
inlineoverridevirtual |
Sum a rank-local element count across the process group.
Distributed vector algorithms use this to distinguish the local slab length from the dimension of the complete vector space.
Implements q3::execution::ExecutionPolicy.
Definition at line 270 of file mpi.hpp.
References group_communicator_, and group_size_.
|
inline |
Definition at line 351 of file mpi.hpp.
References group_index_.
Referenced by q3::execution::PlanewaveMPIExecutionPolicy::global_kpoint_index(), q3::execution::PlanewaveMPIExecutionPolicy::local_kpoint_grid(), and q3::execution::PlanewaveMPIExecutionPolicy::pool_index().
|
inlineoverridevirtual |
Index of this process within its process group.
0 in serial mode. NOT necessarily 0 when group_size() == 1: a group whose data distribution was disabled at run time (see MPIExecutionPolicy::disable_group_distribution) reports group_size() == 1 while keeping its pool-local rank index, because the pool identity is still needed. Use group_size() <= 1 to ask "is my data replicated"; use group_rank_index() == 0 only to pick one representative per pool.
Implements q3::execution::ExecutionPolicy.
Definition at line 258 of file mpi.hpp.
References group_rank_index_.
|
inlineoverridevirtual |
Number of processes in this process group. Always 1 in serial mode or when each group contains a single process.
Implements q3::execution::ExecutionPolicy.
Definition at line 262 of file mpi.hpp.
References group_size_.
Referenced by configure_group_topology(), and q3::execution::PlanewaveMPIExecutionPolicy::create_fft_grid().
|
inlineoverridevirtual |
Check if this process is the root process (rank 0 in the world communicator).
Used by entry points to ensure only one process writes output files or logs non-essential information.
Implements q3::execution::ExecutionPolicy.
|
inlineoverridevirtual |
Norm of a (possibly distributed) coefficient vector.
Delegates to dot_product which handles the group reduction.
Implements q3::execution::ExecutionPolicy.
Definition at line 249 of file mpi.hpp.
References dot_product().
|
inlineoverridevirtual |
Number of processes in the complete execution topology.
Implements q3::execution::ExecutionPolicy.
|
delete |
|
inlineoverridevirtual |
Sum an array across the band split, so that a quantity accumulated from disjoint band ranges (the charge density above all) becomes whole. No-op when bands are not distributed.
Reimplemented from q3::execution::ExecutionPolicy.
Definition at line 428 of file mpi.hpp.
References band_distribution_size_, and group_communicator_.
|
inlineoverridevirtual |
Reduce group-distributed results across the process group.
Used specifically by the task-group H|ψ⟩ path where different ranks compute disjoint contributions to the same array and need to sum them. Unlike reduce_within_group (which is a no-op for replicated data), this always performs the Allreduce.
Reimplemented from q3::execution::ExecutionPolicy.
Definition at line 310 of file mpi.hpp.
References group_communicator_, group_size_, and q3::execution::sum_complex_in_place().
|
inlineoverridevirtual |
Allreduce complex data within the process group.
With data distribution, inner products (e.g. subspace matrices, orthogonalization overlaps) contract over local elements and need to be summed across group ranks.
Implements q3::execution::ExecutionPolicy.
Definition at line 286 of file mpi.hpp.
References group_communicator_, group_size_, and q3::execution::sum_complex_in_place().
|
inlineoverridevirtual |
Allreduce real data within the process group.
Implements q3::execution::ExecutionPolicy.
Definition at line 295 of file mpi.hpp.
References group_communicator_, and group_size_.
|
inline |
Definition at line 345 of file mpi.hpp.
Referenced by q3::execution::PlanewaveMPIExecutionPolicy::configure_topology().
|
inline |
|
protected |
Definition at line 437 of file mpi.hpp.
Referenced by band_distribution_rank_index(), and enable_band_distribution().
|
protected |
Definition at line 436 of file mpi.hpp.
Referenced by allgather_across_bands(), band_distribution_size(), broadcast_across_bands(), broadcast_across_bands(), broadcast_across_bands(), enable_band_distribution(), and reduce_across_bands().
|
protected |
Definition at line 438 of file mpi.hpp.
Referenced by MPIExecutionPolicy(), ~MPIExecutionPolicy(), allgather_across_bands(), allgather_within_group(), broadcast_across_bands(), broadcast_across_bands(), broadcast_across_bands(), broadcast_from_group_root(), broadcast_from_group_root(), configure_group_topology(), dot_product(), get_group_communicator(), global_number_of_elements(), reduce_across_bands(), reduce_group_distributed_result(), reduce_within_group(), and reduce_within_group().
|
protected |
Definition at line 441 of file mpi.hpp.
Referenced by MPIExecutionPolicy(), configure_group_topology(), and group_index().
|
protected |
Definition at line 439 of file mpi.hpp.
Referenced by MPIExecutionPolicy(), q3::execution::PlanewaveMPIExecutionPolicy::assemble_global_kpoint_state_data(), configure_group_topology(), q3::execution::PlanewaveMPIExecutionPolicy::configure_topology(), enable_band_distribution(), and group_rank_index().
|
protected |
Definition at line 440 of file mpi.hpp.
Referenced by MPIExecutionPolicy(), allgather_within_group(), broadcast_from_group_root(), broadcast_from_group_root(), configure_group_topology(), disable_group_distribution(), dot_product(), enable_band_distribution(), global_number_of_elements(), group_size(), reduce_group_distributed_result(), reduce_within_group(), reduce_within_group(), q3::execution::PlanewaveMPIExecutionPolicy::reduce_within_pool_scalar(), and q3::execution::PlanewaveMPIExecutionPolicy::reduce_within_pool_vector().
 1.9.8