#include <init.hpp>
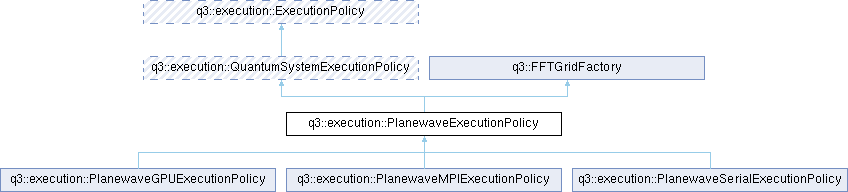
 Inheritance diagram for q3::execution::PlanewaveExecutionPolicy:
Public Member Functions | |
| ~PlanewaveExecutionPolicy () override=default | |
| virtual std::vector< Real > | assemble_global_kpoint_state_data (const std::vector< Real > &local_data, int local_number_of_physical_kpoints, int number_of_spin_components, int number_of_values_per_state) const =0 |
| virtual void | disable_band_distribution () |
| virtual bool | each_process_owns_whole_kpoints () const =0 |
| generated::ResultsExecution | execution_record () const |
| virtual int | global_kpoint_index (int local_kpoint_index) const =0 |
| virtual KPointsGrid | local_kpoint_grid (const KPointsGrid &global_kpoint_grid) const =0 |
| virtual int | number_of_pools () const =0 |
| virtual bool | number_of_pools_was_requested () const |
| virtual bool | one_process_owns_complete_state () const =0 |
| virtual void | reconfigure_topology (int) |
| virtual void | reduce_band_group_scalar_min (int &value) const =0 |
| virtual void | reduce_charge_density (std::vector< std::vector< Real > > &charge_density) const =0 |
| virtual void | reduce_scalar (Real &value) const =0 |
| virtual void | reduce_scalar_max (int &value) const =0 |
| virtual void | reduce_scalar_max (Real &value) const =0 |
| virtual void | reduce_scalar_min (Real &value) const =0 |
| virtual void | reduce_vector (std::vector< Real > &values) const =0 |
| virtual void | reduce_within_pool_scalar (Real &value) const =0 |
| virtual void | reduce_within_pool_vector (std::vector< Real > &values) const =0 |
| Public Member Functions inherited from q3::execution::QuantumSystemExecutionPolicy | |
| ~QuantumSystemExecutionPolicy () override=default | |
| int | band_rank_index () const |
| int | band_size () const |
| Public Member Functions inherited from q3::execution::ExecutionPolicy | |
| virtual | ~ExecutionPolicy ()=default |
| virtual void | add_scaled_vector (int number_of_elements, ComplexValue scaling_factor, const ComplexValue *vector_x, ComplexValue *vector_y) const =0 |
| virtual void | allgather_across_bands (ComplexValue *, const int *, const int *) const |
| virtual void | allgather_within_group (const Real *local_data, int local_count, Real *full_data, int total_count) const =0 |
| virtual int | band_distribution_rank_index () const |
| virtual int | band_distribution_size () const |
| virtual void | broadcast_across_bands (ComplexValue *, int) const |
| virtual void | broadcast_across_bands (int *, int) const |
| Integer overload, for the counts that decide collective sizes. | |
| virtual void | broadcast_across_bands (Real *, int) const |
| Real overload, for eigenvalues – the numbers convergence decisions are made from. | |
| virtual void | broadcast_from_group_root (ComplexValue *, int) const |
| virtual void | broadcast_from_group_root (Real *, int) const |
| virtual ComplexValue | dot_product (int number_of_elements, const ComplexValue *vector_x, const ComplexValue *vector_y) const =0 |
| virtual int | global_number_of_elements (int local_number_of_elements) const =0 |
| virtual int | group_rank_index () const =0 |
| virtual int | group_size () const =0 |
| virtual bool | is_root () const =0 |
| virtual Real | norm (int number_of_elements, const ComplexValue *vector_x) const =0 |
| virtual int | number_of_processes () const =0 |
| virtual void | reduce_across_bands (Real *, int) const |
| virtual void | reduce_group_distributed_result (ComplexValue *, int) const |
| virtual void | reduce_within_group (ComplexValue *data, int number_of_elements) const =0 |
| virtual void | reduce_within_group (Real *data, int number_of_elements) const =0 |
| Public Member Functions inherited from q3::FFTGridFactory | |
| virtual | ~FFTGridFactory ()=default |
| virtual std::unique_ptr< FFTGrid > | create_fft_grid () const =0 |
Additional Inherited Members | |
| Public Types inherited from q3::execution::ExecutionPolicy | |
| using | ComplexValue = Complex |
|
overridedefault |
|
pure virtual |
Assemble fixed-width data for local k-point states into global order.
Local state order is spin-major, with physical k-points ordered as they appear in local_kpoint_grid(). The returned data uses the same spin-major convention over the complete global grid. Serial policies return the input unchanged; MPI policies gather one contribution per pool.
Implemented in q3::execution::PlanewaveMPIExecutionPolicy, q3::execution::PlanewaveGPUExecutionPolicy, and q3::execution::PlanewaveSerialExecutionPolicy.
Referenced by q3::assemble_global_eigenvalues_at_kpoints(), q3::assemble_global_kpoint_state_blocks(), q3::PlanewaveKohnShamSCFIterator::global_eigenvalues(), q3::PlanewaveKohnShamSCFIterator::log_representation_summary(), and q3::PlanewaveKohnShamSCFIterator::report_convergence_details().
|
inlinevirtual |
Disable G-vector distribution, making band-group reductions into no-ops.
Called when slab-based PW distribution yields zero plane waves for some ranks. Default is a no-op (serial policy never distributes G-vectors).
Reimplemented in q3::execution::PlanewaveMPIExecutionPolicy.
Definition at line 55 of file init.hpp.
Referenced by q3::PlanewaveKohnShamSCFIterator::build_kpoint_plane_wave_data().
|
pure virtual |
Whether every process holds the whole of each k-point it works on: all of that k-point's plane-wave coefficients, and the complete density grid.
True exactly when each k-point pool is a single process. Pools still divide the k-points between them, so this is weaker than one_process_owns_complete_state(), but it is enough for a writer whose output splits by k-point: each process writes its own k-points under their global_kpoint_index(), and what pools reduce – the density, the potential built from it – is already whole on every process. Ranks sharing a pool split both the coefficients and the grid, and nothing gathers them yet.
Implemented in q3::execution::PlanewaveGPUExecutionPolicy, q3::execution::PlanewaveMPIExecutionPolicy, and q3::execution::PlanewaveSerialExecutionPolicy.
Referenced by q3::PlanewavePseudopotentialKohnShamSCFIterator::write_checkpoints().
|
inline |
What the run executed on – processes, k-point pools, ranks per pool, the threads each process may use, whether reciprocal space was split, and the peak resident memory of the largest rank – as results.json's runtime_log.execution, so a results file says which policy produced it.
Collective under MPI: every rank must call it, for the memory reduction.
Definition at line 258 of file init.hpp.
References q3::execution::QuantumSystemExecutionPolicy::band_size(), q3::ProfilingCounters::instance(), q3::execution::threading::maximum_threads(), number_of_pools(), q3::execution::ExecutionPolicy::number_of_processes(), q3::ProfilingCounters::peak_resident_bytes_now(), and reduce_scalar_max().
Referenced by q3::SelfConsistentFieldFlavor::run_calculation().
|
pure virtual |
The position in the global k-point grid of this pool's k-point local_kpoint_index, as ordered in local_kpoint_grid().
Identity in serial; under pools, the inverse of the round-robin distribution.
Implemented in q3::execution::PlanewaveGPUExecutionPolicy, q3::execution::PlanewaveMPIExecutionPolicy, and q3::execution::PlanewaveSerialExecutionPolicy.
|
pure virtual |
create_fft_grid() is inherited (pure) from FFTGridFactory — the layer-3 interface through which PlanewaveFFTPair obtains grids without an upward dependency on this class. Compute the local k-point grid assigned to this process's pool.
Serial: returns the global grid unchanged (identity). MPI: distributes k-points round-robin across pools.
| global_kpoint_grid | The full IBZ k-point grid. |
Implemented in q3::execution::PlanewaveGPUExecutionPolicy, q3::execution::PlanewaveMPIExecutionPolicy, and q3::execution::PlanewaveSerialExecutionPolicy.
Referenced by q3::create_kohn_sham_iterator().
|
pure virtual |
Number of k-point pools in the current topology.
Returns 1 in serial mode. In MPI mode returns the number of pools configured by configure_topology(). Used by the factory to validate that no pool is left empty (which would cause MPI collective mismatches).
Implemented in q3::execution::PlanewaveGPUExecutionPolicy, q3::execution::PlanewaveMPIExecutionPolicy, and q3::execution::PlanewaveSerialExecutionPolicy.
Referenced by q3::PlanewaveKohnShamSCFIterator::compute_residual_between(), q3::create_kohn_sham_iterator(), execution_record(), q3::PlanewaveKohnShamSCFIterator::log_representation_summary(), q3::PlanewaveKohnShamSCFIterator::report_convergence_details(), and q3::PlanewavePseudopotentialKohnShamSCFIterator::write_checkpoints().
|
inlinevirtual |
Whether the pool count came from the caller rather than a default.
The factory needs the distinction: an explicit choice is honoured as given, while an unrequested one is chosen from the k-point count. Serial runs report true, since their single pool is not a fallback.
Reimplemented in q3::execution::PlanewaveMPIExecutionPolicy.
Definition at line 87 of file init.hpp.
Referenced by q3::create_kohn_sham_iterator().
|
pure virtual |
Whether one process owns every k-point and every G-vector coefficient.
Writers without a gather implementation may serialize state only when this is true. It is stronger than checking the current group size because a small-basis fallback can disable coefficient distribution without turning a multi-process FFT grid into a serial one.
Implemented in q3::execution::PlanewaveGPUExecutionPolicy, q3::execution::PlanewaveMPIExecutionPolicy, and q3::execution::PlanewaveSerialExecutionPolicy.
Referenced by q3::capture_interpolation_record(), and q3::export_and_record_mean_field_under_topology().
|
inlinevirtual |
Reconfigure the k-point pool topology after initial setup.
Called by the factory when the requested pool count exceeds the number of available IBZ k-points. The implementation clamps the pool count to new_number_of_pools and reconfigures all MPI communicators accordingly.
The default implementation is a no-op: the serial policy always has exactly one pool so clamping is never needed there.
| new_number_of_pools | New (clamped) pool count. |
Reimplemented in q3::execution::PlanewaveMPIExecutionPolicy.
|
pure virtual |
Reduce an integer scalar within the band group using MPI_MIN.
Used during initialization to check if any rank in the pool received zero plane waves from slab distribution.
| value | In-out: local value, replaced by band-group minimum. |
Implemented in q3::execution::PlanewaveGPUExecutionPolicy, q3::execution::PlanewaveSerialExecutionPolicy, and q3::execution::PlanewaveMPIExecutionPolicy.
Referenced by q3::PlanewaveKohnShamSCFIterator::build_kpoint_plane_wave_data().
|
pure virtual |
|
pure virtual |
── Across-pool reductions (inter-pool communicator) ──────────────────────
Use for k-point-local quantities that must be summed across pools. With 1-rank-per-pool these happen over MPI_COMM_WORLD; with multiple ranks per pool they use the inter-pool communicator (one rank per pool). Reduce a scalar k-point sum across all pools (MPI_SUM).
Used for band_energy and smearing_entropy after local k-point accumulation.
| value | In-out: local k-point contribution, replaced by global sum. |
Implemented in q3::execution::PlanewaveGPUExecutionPolicy, q3::execution::PlanewaveSerialExecutionPolicy, and q3::execution::PlanewaveMPIExecutionPolicy.
Referenced by q3::PlanewaveKohnShamSCFIterator::compute_energy_components(), and q3::PlanewavePseudopotentialKohnShamSCFIterator::initialize_single_particle_states().
|
pure virtual |
Reduce a scalar across all pools using MPI_MAX.
Used for summary statistics such as max_plane_waves_per_kpoint where each pool holds only its local k-points and the global maximum is needed.
| value | In-out: local maximum, replaced by global maximum. |
Implemented in q3::execution::PlanewaveGPUExecutionPolicy, q3::execution::PlanewaveSerialExecutionPolicy, and q3::execution::PlanewaveMPIExecutionPolicy.
Referenced by q3::PlanewaveKohnShamSCFIterator::compute_residual_between(), execution_record(), and q3::PlanewaveKohnShamSCFIterator::log_representation_summary().
|
pure virtual |
Reduce a Real scalar across all pools using MPI_MAX.
Used for global eigenvalue range (e.g., HOMO across pools).
| value | In-out: local maximum, replaced by global maximum. |
Implemented in q3::execution::PlanewaveGPUExecutionPolicy, q3::execution::PlanewaveSerialExecutionPolicy, and q3::execution::PlanewaveMPIExecutionPolicy.
|
pure virtual |
Reduce a Real scalar across all pools using MPI_MIN.
Used for global eigenvalue range (e.g., LUMO across pools).
| value | In-out: local minimum, replaced by global minimum. |
Implemented in q3::execution::PlanewaveGPUExecutionPolicy, q3::execution::PlanewaveSerialExecutionPolicy, and q3::execution::PlanewaveMPIExecutionPolicy.
|
pure virtual |
Reduce a vector of k-point-local values across all pools (MPI_SUM).
Used for nonlocal forces and kinetic/nonlocal stress contributions.
| values | In-out: local k-point contributions, replaced by global sum. |
Implemented in q3::execution::PlanewaveGPUExecutionPolicy, q3::execution::PlanewaveSerialExecutionPolicy, and q3::execution::PlanewaveMPIExecutionPolicy.
Referenced by q3::PlanewavePseudopotentialKohnShamSCFIterator::accumulate_hubbard_occupation_and_potential(), q3::UltrasoftPlanewavePseudopotentialKohnShamSCFIterator::accumulate_projector_overlaps(), q3::ForceCalculator::compute_forces(), and q3::compute_stress().
|
pure virtual |
── Within-pool reductions (band communicator) ────────────────────────────
Use for real-space slab integrals. With 1-rank-per-pool these are no-ops. With multiple ranks per pool, FFTW-MPI distributes the real-space grid across the band communicator; each rank integrates only its local slabs and these methods sum the partial results within the pool. Reduce a real-space slab integral scalar within this pool (MPI_SUM).
Used for XC energy, double-counting correction, and delta-eSCF correction.
| value | In-out: partial slab integral, replaced by pool-total. |
Implemented in q3::execution::PlanewaveGPUExecutionPolicy, q3::execution::PlanewaveSerialExecutionPolicy, and q3::execution::PlanewaveMPIExecutionPolicy.
Referenced by q3::PlanewaveEffectivePotentialCalculator::compute(), q3::PlanewaveKohnShamSCFIterator::compute_delta_escf_correction(), q3::PlanewaveKohnShamSCFIterator::compute_double_counting_correction(), and q3::PlanewaveKohnShamSCFIterator::report_convergence_details().
|
pure virtual |
Reduce a real-space slab integral vector within this pool (MPI_SUM).
Used for local forces, XC stress, local-PP stress, and core-correction forces/stress computed from real-space grid slabs.
| values | In-out: partial slab contributions, replaced by pool-total. |
Implemented in q3::execution::PlanewaveGPUExecutionPolicy, q3::execution::PlanewaveSerialExecutionPolicy, and q3::execution::PlanewaveMPIExecutionPolicy.
Referenced by q3::MakovPayneCorrectionCalculator::compute(), q3::MartynaTuckermanCorrectionCalculator::compute(), q3::compute_stress(), q3::PlanewaveKohnShamSCFIterator::initiate_mixer(), and q3::NormConservingPlanewaveWavefunctionInitializer::rotate_wavefunctions().
 1.9.8