#include <mpi.hpp>
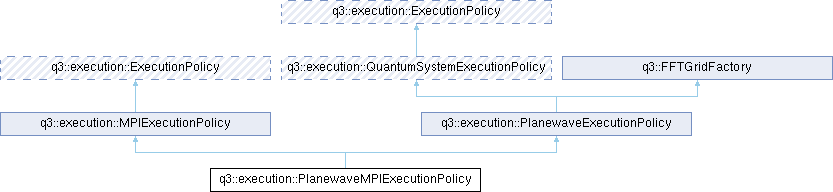
 Inheritance diagram for q3::execution::PlanewaveMPIExecutionPolicy:
Public Member Functions | |
| PlanewaveMPIExecutionPolicy () | |
| PlanewaveMPIExecutionPolicy (const PlanewaveMPIExecutionPolicy &)=delete | |
| ~PlanewaveMPIExecutionPolicy () override | |
| std::vector< Real > | assemble_global_kpoint_state_data (const std::vector< Real > &local_data, int local_number_of_physical_kpoints, int number_of_spin_components, int number_of_values_per_state) const override |
| void | configure_topology (int requested_number_of_pools) |
| std::unique_ptr< FFTGrid > | create_fft_grid () const override |
| void | disable_band_distribution () override |
| bool | each_process_owns_whole_kpoints () const override |
| int | global_kpoint_index (int local_kpoint_index) const override |
| KPointsGrid | local_kpoint_grid (const KPointsGrid &global_kpoint_grid) const override |
| int | number_of_pools () const override |
| bool | number_of_pools_was_requested () const override |
| bool | one_process_owns_complete_state () const override |
| PlanewaveMPIExecutionPolicy & | operator= (const PlanewaveMPIExecutionPolicy &)=delete |
| int | pool_index () const |
| void | reconfigure_topology (int new_number_of_pools) override |
| void | reduce_band_group_scalar_min (int &value) const override |
| void | reduce_charge_density (std::vector< std::vector< Real > > &charge_density) const override |
| void | reduce_scalar (Real &value) const override |
| void | reduce_scalar_max (int &value) const override |
| void | reduce_scalar_max (Real &value) const override |
| void | reduce_scalar_min (Real &value) const override |
| void | reduce_vector (std::vector< Real > &values) const override |
| void | reduce_within_pool_scalar (Real &value) const override |
| void | reduce_within_pool_vector (std::vector< Real > &values) const override |
| Public Member Functions inherited from q3::execution::MPIExecutionPolicy | |
| MPIExecutionPolicy () | |
| MPIExecutionPolicy (const MPIExecutionPolicy &)=delete | |
| ~MPIExecutionPolicy () override | |
| void | add_scaled_vector (int number_of_elements, ComplexValue scaling_factor, const ComplexValue *vector_x, ComplexValue *vector_y) const override |
| void | allgather_across_bands (ComplexValue *data, const int *counts, const int *displacements) const override |
| void | allgather_within_group (const Real *local_data, int local_count, Real *full_data, int) const override |
| int | band_distribution_rank_index () const override |
| int | band_distribution_size () const override |
| void | broadcast_across_bands (ComplexValue *data, int number_of_elements) const override |
| void | broadcast_across_bands (int *data, int number_of_elements) const override |
| Integer overload, for the counts that decide collective sizes. | |
| void | broadcast_across_bands (Real *data, int number_of_elements) const override |
| Real overload, for eigenvalues – the numbers convergence decisions are made from. | |
| void | broadcast_from_group_root (ComplexValue *data, int number_of_elements) const override |
| void | broadcast_from_group_root (Real *data, int number_of_elements) const override |
| void | configure_group_topology (int number_of_groups) |
| void | disable_group_distribution () |
| ComplexValue | dot_product (int number_of_elements, const ComplexValue *vector_x, const ComplexValue *vector_y) const override |
| void | enable_band_distribution () |
| MPI_Comm | get_group_communicator () const |
| MPI_Comm | get_world_communicator () const |
| int | global_number_of_elements (int local_number_of_elements) const override |
| int | group_index () const |
| int | group_rank_index () const override |
| int | group_size () const override |
| bool | is_root () const override |
| Real | norm (int number_of_elements, const ComplexValue *vector_x) const override |
| int | number_of_processes () const override |
| MPIExecutionPolicy & | operator= (const MPIExecutionPolicy &)=delete |
| void | reduce_across_bands (Real *data, int number_of_elements) const override |
| void | reduce_group_distributed_result (ComplexValue *data, int number_of_elements) const override |
| void | reduce_within_group (ComplexValue *data, int number_of_elements) const override |
| void | reduce_within_group (Real *data, int number_of_elements) const override |
| int | world_rank_index () const |
| int | world_size () const |
| Public Member Functions inherited from q3::execution::ExecutionPolicy | |
| virtual | ~ExecutionPolicy ()=default |
| Public Member Functions inherited from q3::execution::PlanewaveExecutionPolicy | |
| ~PlanewaveExecutionPolicy () override=default | |
| generated::ResultsExecution | execution_record () const |
| Public Member Functions inherited from q3::execution::QuantumSystemExecutionPolicy | |
| ~QuantumSystemExecutionPolicy () override=default | |
| int | band_rank_index () const |
| int | band_size () const |
| Public Member Functions inherited from q3::FFTGridFactory | |
| virtual | ~FFTGridFactory ()=default |
Additional Inherited Members | |
| Public Types inherited from q3::execution::ExecutionPolicy | |
| using | ComplexValue = Complex |
| Protected Attributes inherited from q3::execution::MPIExecutionPolicy | |
| int | band_distribution_rank_index_ = 0 |
| int | band_distribution_size_ = 1 |
| MPI_Comm | group_communicator_ = MPI_COMM_NULL |
| int | group_index_ = 0 |
| int | group_rank_index_ = 0 |
| int | group_size_ = 1 |
|
inline |
Initialize MPI (via MPIExecutionPolicy), then split into k-point pools.
Each process starts with 1 pool (all ranks in one band group) until configure_topology() is called. Quantum ESPRESSO's initial default is also a single pool, but note it does not stop there: when the rank count is large relative to the FFT z-dimension and more than one k-point exists, it raises the pool count on its own. Q3 never does – the pool count is whatever the caller asked for.
|
inlineoverride |
Free the inter-pool communicator, unless an exception is in flight.
MPI_Comm_free is collective, and this destructor runs ahead of ~MPIExecutionPolicy() on the same object, so it declines for the same reason and must decline independently: a base class skipping its teardown does nothing for a derived one that goes first. Open MPI happens to complete this call without synchronizing, which is why the hang reproduced in ~MPIExecutionPolicy()'s barrier rather than here, but the standard makes it collective and an implementation is free to make it block – so this cannot be left to rest on which MPI is installed.
|
delete |
|
inlineoverridevirtual |
Assemble fixed-width data for local k-point states into global order.
Local state order is spin-major, with physical k-points ordered as they appear in local_kpoint_grid(). The returned data uses the same spin-major convention over the complete global grid. Serial policies return the input unchanged; MPI policies gather one contribution per pool.
Implements q3::execution::PlanewaveExecutionPolicy.
Definition at line 306 of file mpi.hpp.
References global_kpoint_index(), and q3::execution::MPIExecutionPolicy::group_rank_index_.
|
inline |
Configure the parallel topology from the user-requested pool count.
All pool topology logic lives here so that callers (main, factory) need no knowledge of what a "pool" is or how ranks are distributed.
| requested_number_of_pools | Number of k-point pools requested by the user. Pass 0 to default to 1 pool (all ranks share one band group — matching QE's default band/FFT parallelism behaviour). |
| std::invalid_argument | if world_size is not divisible by the pool count. |
Create inter-pool communicator: ranks with the same group_rank_index_ work on the same grid slabs across different pools (k-point parallel groups).
Definition at line 73 of file mpi.hpp.
References q3::execution::MPIExecutionPolicy::configure_group_topology(), q3::execution::MPIExecutionPolicy::group_rank_index_, number_of_pools(), q3::execution::MPIExecutionPolicy::world_rank_index(), and q3::execution::MPIExecutionPolicy::world_size().
Referenced by reconfigure_topology().
|
inlineoverridevirtual |
Create a new FFT grid instance appropriate for the active execution configuration (serial, MPI slab-decomposed, ...).
When running with a single rank per band group (np=1), use the serial FFT grid which supports FFTW threading (OMP_NUM_THREADS). This avoids MPI FFT overhead and enables hybrid thread parallelism for FFTs.
Ranks sharing a pool distribute reciprocal space by stick. The FFTW-MPI slab grid it replaces split a plane from its mirror, which is what forced gamma-only off under MPI, and divided unevenly enough to leave ranks empty at eight. The stick grid needs only serial FFTW plus MPI.
Implements q3::FFTGridFactory.
Definition at line 363 of file mpi.hpp.
References q3::execution::MPIExecutionPolicy::get_group_communicator(), and q3::execution::MPIExecutionPolicy::group_size().
|
inlineoverridevirtual |
── Collective vector ops: inherited from MPIExecutionPolicy ────────────── dot_product, add_scaled_vector, norm — reduce over the group communicator
Reimplemented from q3::execution::PlanewaveExecutionPolicy.
Definition at line 145 of file mpi.hpp.
References q3::execution::MPIExecutionPolicy::disable_group_distribution().
|
inlineoverridevirtual |
One rank per pool. Decided from the topology, not from group_size(): a pool whose coefficient distribution was switched off reports a group of one while its ranks still divide the FFT grid.
Implements q3::execution::PlanewaveExecutionPolicy.
Definition at line 402 of file mpi.hpp.
References q3::execution::MPIExecutionPolicy::world_size().
|
inlineoverridevirtual |
Pool p holds global k-points p, p + P, p + 2P, ... – the round-robin KPointDistributor deals out in local_kpoint_grid().
Implements q3::execution::PlanewaveExecutionPolicy.
Definition at line 410 of file mpi.hpp.
References q3::execution::MPIExecutionPolicy::group_index().
Referenced by assemble_global_kpoint_state_data().
|
inlineoverridevirtual |
Distribute k-points round-robin across pools; return this pool's subset.
Implements q3::execution::PlanewaveExecutionPolicy.
Definition at line 299 of file mpi.hpp.
References q3::execution::MPIExecutionPolicy::group_index(), and q3::parallel::KPointDistributor::local_kpoint_grid().
|
inlineoverridevirtual |
Number of k-point pools in the current topology.
Returns 1 in serial mode. In MPI mode returns the number of pools configured by configure_topology(). Used by the factory to validate that no pool is left empty (which would cause MPI collective mismatches).
Implements q3::execution::PlanewaveExecutionPolicy.
Definition at line 390 of file mpi.hpp.
Referenced by configure_topology().
|
inlineoverridevirtual |
Whether the pool count came from the caller rather than a default.
The factory needs the distinction: an explicit choice is honoured as given, while an unrequested one is chosen from the k-point count. Serial runs report true, since their single pool is not a fallback.
Reimplemented from q3::execution::PlanewaveExecutionPolicy.
|
inlineoverridevirtual |
Whether one process owns every k-point and every G-vector coefficient.
Writers without a gather implementation may serialize state only when this is true. It is stronger than checking the current group size because a small-basis fallback can disable coefficient distribution without turning a multi-process FFT grid into a serial one.
Implements q3::execution::PlanewaveExecutionPolicy.
Definition at line 393 of file mpi.hpp.
References q3::execution::MPIExecutionPolicy::world_size().
|
delete |
|
inline |
Definition at line 383 of file mpi.hpp.
References q3::execution::MPIExecutionPolicy::group_index().
|
inlineoverridevirtual |
Reconfigure the parallel topology after initial setup.
Called by the factory when it needs to clamp the pool count to the number of available IBZ k-points (e.g., when –pools 4 is requested but only 2 k-points exist). Delegates to configure_topology with the new count.
| new_number_of_pools | Clamped pool count (must be <= original count). |
Reimplemented from q3::execution::PlanewaveExecutionPolicy.
Definition at line 109 of file mpi.hpp.
References configure_topology().
|
inlineoverridevirtual |
Allreduce an integer scalar within the band group using MPI_MIN.
Uses the band communicator so that ranks within the same pool can collectively determine the minimum plane-wave count.
Implements q3::execution::PlanewaveExecutionPolicy.
Definition at line 260 of file mpi.hpp.
References q3::execution::MPIExecutionPolicy::get_group_communicator().
|
inlineoverridevirtual |
Allreduce spin-resolved charge density across all k-point pools.
Uses the inter-pool communicator (grouped by group_rank_index_) so that each slab of the real-space rho grid is summed across matching band-rank positions in different pools: rank i of pool 0 reduces with rank i of pool 1, etc. This correctly accumulates k-point contributions while keeping the slab decomposition intact.
When group_size > 1, band ranks within the same pool hold non-overlapping slab portions of the rho grid at different LOCAL indices. These must NOT be Allreduced within the pool (that would add incompatible grid points). Each band rank's slab is already the correct contribution for that portion of the grid.
Note: single-pool band parallelism (number_of_pools_==1, group_size_>1) is not supported by this Allreduce design. It would require MPI_Allgather to assemble the full density, which requires resizing charge_density_real_ throughout the SCF. That architectural change is deferred.
A zero-length channel still enters the Allreduce. MPI accepts count 0 and never dereferences the buffer, whereas skipping the call on one rank would leave its peers blocked forever. Sizes are uniform here by construction – rank i of every pool owns the same slab of identical grids – but a collective must not depend on that holding.
Implements q3::execution::PlanewaveExecutionPolicy.
|
inlineoverridevirtual |
Allreduce a scalar k-point sum across all pools.
Uses the inter-pool communicator so that only one rank per pool participates, avoiding double-counting when group_size > 1.
Implements q3::execution::PlanewaveExecutionPolicy.
|
inlineoverridevirtual |
Allreduce an integer scalar across all pools using MPI_MAX.
Used for summary statistics (e.g. max_plane_waves_per_kpoint) where each pool holds only its local k-points and the global maximum is required.
Implements q3::execution::PlanewaveExecutionPolicy.
|
inlineoverridevirtual |
Allreduce a Real scalar across all pools using MPI_MAX.
Used for global eigenvalue range (HOMO) in Fermi energy calculation.
Implements q3::execution::PlanewaveExecutionPolicy.
|
inlineoverridevirtual |
Allreduce a Real scalar across all pools using MPI_MIN.
Used for global eigenvalue range (LUMO) in Fermi energy calculation.
Implements q3::execution::PlanewaveExecutionPolicy.
|
inlineoverridevirtual |
Allreduce a k-point-local vector across all pools.
Uses the inter-pool communicator for the same reason as reduce_scalar.
Implements q3::execution::PlanewaveExecutionPolicy.
|
inlineoverridevirtual |
Allreduce a real-space slab integral scalar within this pool.
Uses the band communicator (within-pool) so that all slab contributions from ranks in the same pool are combined. No-op when group_size == 1.
Implements q3::execution::PlanewaveExecutionPolicy.
Definition at line 270 of file mpi.hpp.
References q3::execution::MPIExecutionPolicy::get_group_communicator(), and q3::execution::MPIExecutionPolicy::group_size_.
|
inlineoverridevirtual |
Allreduce a real-space slab integral vector within this pool.
Uses the band communicator for the same reason as reduce_within_pool_scalar.
group_size_ is identical on every rank of the group, so returning on it is safe; the vector's local emptiness is not, and is no longer tested.
Implements q3::execution::PlanewaveExecutionPolicy.
Definition at line 281 of file mpi.hpp.
References q3::execution::MPIExecutionPolicy::get_group_communicator(), and q3::execution::MPIExecutionPolicy::group_size_.
 1.9.8