#include <init.hpp>
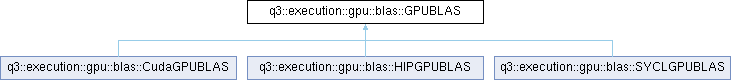
 Inheritance diagram for q3::execution::gpu::blas::GPUBLAS:
Public Member Functions | |
| GPUBLAS (std::shared_ptr< device::GPUDeviceBackend > device_backend) | |
| virtual | ~GPUBLAS ()=default |
| virtual void | axpy (int number_of_elements, Complex scaling_factor, const Complex *vector_x, Complex *vector_y) const =0 |
| device::GPUDeviceBackend & | device_backend () |
| const device::GPUDeviceBackend & | device_backend () const |
| virtual void | dgemm (char transpose_a, char transpose_b, int m, int n, int k, Real alpha, const Real *matrix_a, int leading_dimension_a, const Real *matrix_b, int leading_dimension_b, Real beta, Real *matrix_c, int leading_dimension_c) const =0 |
| virtual Complex | dot_product (int number_of_elements, const Complex *vector_x, const Complex *vector_y) const =0 |
| virtual ComplexSingle | dot_product_single (int number_of_elements, const ComplexSingle *vector_x, const ComplexSingle *vector_y) const =0 |
| virtual void | gemm (char transpose_a, char transpose_b, int m, int n, int k, Complex alpha, const Complex *matrix_a, int leading_dimension_a, const Complex *matrix_b, int leading_dimension_b, Complex beta, Complex *matrix_c, int leading_dimension_c) const =0 |
| virtual void | gemm_single (char transpose_a, char transpose_b, int m, int n, int k, ComplexSingle alpha, const ComplexSingle *matrix_a, int leading_dimension_a, const ComplexSingle *matrix_b, int leading_dimension_b, ComplexSingle beta, ComplexSingle *matrix_c, int leading_dimension_c) const =0 |
| virtual double | norm (int number_of_elements, const Complex *vector_x) const =0 |
| virtual float | norm_single (int number_of_elements, const ComplexSingle *vector_x) const =0 |
| virtual void | scale (int number_of_elements, Complex scaling_factor, Complex *vector_x) const =0 |
Protected Attributes | |
| std::shared_ptr< device::GPUDeviceBackend > | device_backend_ |
|
inlineexplicit |
Construct a GPU BLAS wrapper backed by the given device.
The device backend is used for synchronization. The concrete vendor BLAS handle (cuBLAS, Accelerate) is created internally by the vendor-specific subclass constructor.
| device_backend | Shared pointer to the GPU device backend. Must not be null. |
|
virtualdefault |
|
pure virtual |
Scaled vector addition: vector_y += scaling_factor * vector_x (ZAXPY).
| number_of_elements | Length of both vectors. |
| scaling_factor | Complex scaling coefficient. |
| vector_x | Source vector. |
| vector_y | Destination vector (modified in-place). |
Implemented in q3::execution::gpu::blas::CudaGPUBLAS, q3::execution::gpu::blas::HIPGPUBLAS, and q3::execution::gpu::blas::SYCLGPUBLAS.
Referenced by q3::execution::PlanewaveGPUExecutionPolicy::add_scaled_vector().
|
inline |
Access the underlying GPU device backend.
Definition at line 200 of file init.hpp.
References device_backend_.
|
inline |
Access the underlying GPU device backend (const).
Definition at line 207 of file init.hpp.
References device_backend_.
|
pure virtual |
Real double-precision general matrix-matrix multiply (DGEMM). matrix_c := alpha * op(matrix_a) * op(matrix_b) + beta * matrix_c
Used in gamma-only calculations where wavefunctions are real-valued.
Implemented in q3::execution::gpu::blas::CudaGPUBLAS, q3::execution::gpu::blas::HIPGPUBLAS, and q3::execution::gpu::blas::SYCLGPUBLAS.
Referenced by q3::GPUPlanewaveSubspaceManager::orthogonalize_batch(), and q3::GPUPlanewaveSubspaceManager::update_subspace_matrices().
|
pure virtual |
Complex double-precision conjugated dot product: result = x† · y.
Synchronizes before returning the scalar result.
| number_of_elements | Length of both vectors. |
| vector_x | Left operand (conjugated). |
| vector_y | Right operand. |
Implemented in q3::execution::gpu::blas::CudaGPUBLAS, q3::execution::gpu::blas::HIPGPUBLAS, and q3::execution::gpu::blas::SYCLGPUBLAS.
Referenced by q3::execution::PlanewaveGPUExecutionPolicy::dot_product(), and q3::cli::validate_gpu_blas().
|
pure virtual |
Complex single-precision conjugated dot product: result = x† · y.
Synchronizes before returning the scalar result.
| number_of_elements | Length of both vectors. |
| vector_x | Left operand (conjugated). |
| vector_y | Right operand. |
Implemented in q3::execution::gpu::blas::CudaGPUBLAS, q3::execution::gpu::blas::HIPGPUBLAS, and q3::execution::gpu::blas::SYCLGPUBLAS.
|
pure virtual |
Complex double-precision general matrix-matrix multiply (ZGEMM). matrix_c := alpha * op(matrix_a) * op(matrix_b) + beta * matrix_c
| transpose_a | 'N', 'T', or 'C' for op(matrix_a). |
| transpose_b | 'N', 'T', or 'C' for op(matrix_b). |
| m | Number of rows of op(matrix_a) and matrix_c. |
| n | Number of columns of op(matrix_b) and matrix_c. |
| k | Number of columns of op(matrix_a) / rows of op(matrix_b). |
| alpha | Scalar multiplier for the product. |
| matrix_a | Pointer to matrix A data. |
| leading_dimension_a | Leading dimension of matrix_a. |
| matrix_b | Pointer to matrix B data. |
| leading_dimension_b | Leading dimension of matrix_b. |
| beta | Scalar multiplier for matrix_c. |
| matrix_c | Pointer to matrix C data (in-out). |
| leading_dimension_c | Leading dimension of matrix_c. |
Implemented in q3::execution::gpu::blas::CudaGPUBLAS, q3::execution::gpu::blas::HIPGPUBLAS, and q3::execution::gpu::blas::SYCLGPUBLAS.
Referenced by q3::GPUPlanewaveSubspaceManager::build_correction_vectors(), q3::GPUPlanewaveSubspaceManager::collapse_subspace(), q3::GPUPlanewaveSubspaceManager::extract_eigenvectors(), q3::GPUPlanewaveSubspaceManager::orthogonalize_batch(), and q3::GPUPlanewaveSubspaceManager::update_subspace_matrices().
|
pure virtual |
Complex single-precision general matrix-matrix multiply (CGEMM). matrix_c := alpha * op(matrix_a) * op(matrix_b) + beta * matrix_c
Implemented in q3::execution::gpu::blas::CudaGPUBLAS, q3::execution::gpu::blas::HIPGPUBLAS, and q3::execution::gpu::blas::SYCLGPUBLAS.
|
pure virtual |
Euclidean norm of a complex double-precision vector.
Synchronizes before returning the scalar result.
| number_of_elements | Length of the vector. |
| vector_x | Input vector. |
Implemented in q3::execution::gpu::blas::CudaGPUBLAS, q3::execution::gpu::blas::HIPGPUBLAS, and q3::execution::gpu::blas::SYCLGPUBLAS.
Referenced by q3::execution::PlanewaveGPUExecutionPolicy::norm().
|
pure virtual |
Euclidean norm of a complex single-precision vector.
Synchronizes before returning the scalar result.
| number_of_elements | Length of the vector. |
| vector_x | Input vector. |
Implemented in q3::execution::gpu::blas::CudaGPUBLAS, q3::execution::gpu::blas::HIPGPUBLAS, and q3::execution::gpu::blas::SYCLGPUBLAS.
|
pure virtual |
Scale a complex double-precision vector: vector_x := scaling_factor * vector_x.
| number_of_elements | Length of the vector. |
| scaling_factor | Complex scaling coefficient. |
| vector_x | Vector to scale (in-place). |
Implemented in q3::execution::gpu::blas::CudaGPUBLAS, q3::execution::gpu::blas::HIPGPUBLAS, and q3::execution::gpu::blas::SYCLGPUBLAS.
Referenced by q3::GPUPlanewaveSubspaceManager::build_correction_vectors().
|
protected |
Definition at line 212 of file init.hpp.
Referenced by q3::execution::gpu::blas::SYCLGPUBLAS::SYCLGPUBLAS(), device_backend(), and device_backend().
 1.9.8