Definition at line 36 of file cuda.cpp.
◆ CudaGPUDeviceBackend()
| q3::execution::gpu::device::CudaGPUDeviceBackend::CudaGPUDeviceBackend |
( |
| ) |
|
|
inline |
Construct and initialize the CUDA device backend.
Selects device 0 and queries its properties.
Definition at line 43 of file cuda.cpp.
◆ allocate_unified()
| void * q3::execution::gpu::device::CudaGPUDeviceBackend::allocate_unified |
( |
size_t |
size_bytes | ) |
|
|
inlineoverridevirtual |
Allocate unified (managed) memory via cudaMallocManaged().
Managed memory is accessible from both host and device with automatic page migration. This simplifies the programming model at the cost of some potential performance overhead compared to explicit transfers.
Implements q3::execution::gpu::device::GPUDeviceBackend.
Definition at line 77 of file cuda.cpp.
◆ deallocate()
| void q3::execution::gpu::device::CudaGPUDeviceBackend::deallocate |
( |
void * |
pointer | ) |
|
|
inlineoverridevirtual |
◆ device_name()
| std::string q3::execution::gpu::device::CudaGPUDeviceBackend::device_name |
( |
| ) |
const |
|
inlineoverridevirtual |
◆ supports_double_precision()
| bool q3::execution::gpu::device::CudaGPUDeviceBackend::supports_double_precision |
( |
| ) |
const |
|
inlineoverridevirtual |
◆ synchronize()
| void q3::execution::gpu::device::CudaGPUDeviceBackend::synchronize |
( |
| ) |
|
|
inlineoverridevirtual |
◆ total_memory_bytes()
| size_t q3::execution::gpu::device::CudaGPUDeviceBackend::total_memory_bytes |
( |
| ) |
const |
|
inlineoverridevirtual |
The documentation for this class was generated from the following file:
- src/layer_0_core/execution/gpu/device/cuda.cpp
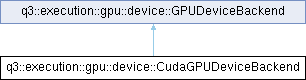
 Inheritance diagram for q3::execution::gpu::device::CudaGPUDeviceBackend:
 1.9.8