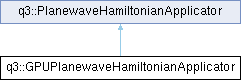#include <gpu.hpp>
 Inheritance diagram for q3::GPUPlanewaveHamiltonianApplicator:
Public Member Functions | |
| GPUPlanewaveHamiltonianApplicator (const Crystal &crystal_structure, const PlanewaveBasis &planewave_basis, const KPointsGrid &kpoint_grid, const NormConservingPlanewaveKohnShamQuantumSystem &pseudopotential_quantum_system, execution::gpu::blas::GPUBLAS &gpu_blas, gpu::GPUFFTGrid *gpu_fft_grid, std::shared_ptr< execution::gpu::device::GPUDeviceBackend > device_backend) | |
| void | apply_batch (const Complex *input_wavefunctions, Complex *output_hamiltonian_wavefunctions, int number_of_vectors) override |
| void | apply_batch_single_precision (const ComplexSingle *input_wavefunctions, ComplexSingle *output_hamiltonian_wavefunctions, int number_of_vectors) |
| const std::vector< Real > & | cached_scaled_potential () const |
| const std::vector< int > & | g_to_fft_mapping () const |
| const q3::Matrix< Complex > * | get_cached_projectors (int) const override |
| void | invalidate_smooth_potential_cache () override |
| bool | is_gamma_only_current () const override |
| bool | is_smooth_potential_cache_valid () const override |
| const std::vector< int > & | minus_g_to_fft_mapping () const |
| void | prepare_kpoint (int kpoint_index, int number_of_plane_waves, const std::vector< int > &g_vector_indices, const std::vector< Real > &kinetic_energy_squared) override |
| void | set_cached_projectors (int, const q3::Matrix< Complex > *) override |
| void | set_use_mixed_precision (bool use_mixed_precision) |
| void | update_potential (const std::vector< Real > &real_space_potential) override |
| Public Member Functions inherited from q3::PlanewaveHamiltonianApplicator | |
| virtual | ~PlanewaveHamiltonianApplicator ()=default |
| virtual bool | gamma_origin_is_local_current () const |
| virtual void | set_cached_hubbard_projectors (int kpoint_index, const q3::Matrix< Complex > *projectors) |
| virtual void | set_hubbard_d_matrix (const std::vector< Complex > *dense_d_matrix_column_major) |
| void | set_spin_channel (int spin_channel) |
| int | spin_channel () const |
Additional Inherited Members | |
| Protected Attributes inherited from q3::PlanewaveHamiltonianApplicator | |
| int | spin_channel_ {0} |
| Spin channel the current potential and D belong to; 0 when unpolarized. | |
|
inline |
Construct with run-constant planewave context and GPU math wrappers.
All references and the shared_ptr must outlive this object.
| crystal_structure | Crystal geometry. |
| planewave_basis | Planewave basis (G-vectors, FFT grids). |
| kpoint_grid | K-point grid for Brillouin zone sampling. |
| pseudopotential_quantum_system | Pseudopotential data (KB projectors, D-matrix). |
| gpu_blas | GPU BLAS wrapper for matrix/vector operations. |
| gpu_fft_grid | GPU FFT grid for potential application. |
| device_backend | GPU device backend for memory allocation. |
Initialize the GPU FFT grid with the wave (smooth) grid dimensions so that cuFFT plans are created before any FFT calls.
Definition at line 66 of file gpu.hpp.
References q3::PlanewaveBasis::fft_wave(), and q3::FFTGrid::init().
|
inlineoverridevirtual |
Apply H|ψ⟩ in double precision (FP64) to a batch of vectors.
Uses GPU BLAS for KB projector application (3× ZGEMM) and CPU-side FFT for the local potential application. The kinetic energy is applied element-wise on the host (unified memory).
All input/output pointers must come from GPUDeviceBuffer (unified memory).
Implements q3::PlanewaveHamiltonianApplicator.
Definition at line 258 of file gpu.hpp.
References q3::execution::gpu::device::GPUDeviceBuffer< T >::data(), q3::PlanewaveBasis::fft_wave(), q3::diagonalizer::planewave::gpu::launch_apply_kinetic_energy(), q3::FFTGrid::local_grid_points(), and q3::execution::gpu::device::GPUDeviceBuffer< T >::size().
|
inline |
Apply H|ψ⟩ in single precision (FP32) to a batch of vectors.
Identical algorithm to apply_batch() but operates on ComplexSingle arrays and uses FP32 BLAS/FFT calls. Used by the mixed-precision Davidson loop for bulk iterations before switchover.
Definition at line 313 of file gpu.hpp.
References q3::execution::gpu::device::GPUDeviceBuffer< T >::data(), q3::PlanewaveBasis::fft_wave(), q3::gpu::GPUFFTGrid::forward_single_batch(), q3::gpu::GPUFFTGrid::inverse_raw_single_batch(), q3::PlanewaveBasis::is_gamma_only(), q3::diagonalizer::planewave::gpu::launch_apply_kinetic_energy_single(), q3::diagonalizer::planewave::gpu::launch_gather_fft_grid_to_g_single(), q3::diagonalizer::planewave::gpu::launch_multiply_potential_single(), q3::diagonalizer::planewave::gpu::launch_scatter_g_to_fft_grid_single(), q3::FFTGrid::local_grid_points(), and q3::execution::gpu::device::GPUDeviceBuffer< T >::size().
|
inline |
|
inline |
|
inlineoverridevirtual |
Returns nullptr — GPU applicator manages projectors internally.
Reimplemented from q3::PlanewaveHamiltonianApplicator.
|
inlineoverridevirtual |
Invalidate any cached smooth potential. Called when the effective potential changes (e.g., at start of each SCF iteration).
Implements q3::PlanewaveHamiltonianApplicator.
|
inlineoverridevirtual |
Report whether the current k-point is gamma-only.
This affects dot product computations in the subspace manager: gamma-only uses 2×Re(z·z*) instead of complex zdotc.
Reimplemented from q3::PlanewaveHamiltonianApplicator.
Definition at line 430 of file gpu.hpp.
References q3::PlanewaveBasis::is_gamma_only().
|
inlineoverridevirtual |
Whether the smooth potential cache is currently valid.
Reimplemented from q3::PlanewaveHamiltonianApplicator.
|
inline |
|
inlineoverridevirtual |
Configure for a specific k-point.
Copies G-to-FFT mapping, kinetic energy factors, and KB projectors to GPUDeviceBuffers. The KB projectors are computed on CPU and then transferred to the GPU.
Implements q3::PlanewaveHamiltonianApplicator.
Definition at line 167 of file gpu.hpp.
References q3::NormConservingPlanewaveBasis::beta_function_table(), q3::precision::cast_double_to_single(), q3::precision::cast_real_double_to_single(), q3::compute_kleinman_bylander_projectors(), q3::Matrix< T >::data(), q3::execution::gpu::device::GPUDeviceBuffer< T >::data(), q3::Matrix< T >::empty(), q3::PlanewaveBasis::is_gamma_only(), q3::NormConservingPlanewaveKohnShamQuantumSystem::pseudopotential_basis(), q3::NormConservingPlanewaveBasis::pseudopotential_set(), q3::Matrix< T >::rows(), and q3::NormConservingPlanewaveBasis::total_number_of_projectors().
|
inlineoverridevirtual |
No-op: GPU applicator computes projectors internally in prepare_kpoint().
Reimplemented from q3::PlanewaveHamiltonianApplicator.
|
inline |
Enable or disable mixed-precision mode.
When enabled, apply_batch() runs the local potential FFT section in FP32 (scatter FP64→FP32, FFT, V*ψ, FFT, gather FP32→FP64). Kinetic energy and nonlocal projectors remain in FP64. This gives most of the GPU FP32 speedup without restructuring the Davidson loop.
Definition at line 115 of file gpu.hpp.
References q3::log::info().
|
inlineoverridevirtual |
Update the effective potential for a new SCF iteration.
Computes the smooth-grid potential on CPU (same as serial), then copies the result to a GPUDeviceBuffer for GPU-side V(r)·ψ(r) multiplication.
Implements q3::PlanewaveHamiltonianApplicator.
Definition at line 129 of file gpu.hpp.
References q3::precision::cast_real_double_to_single(), q3::execution::gpu::device::GPUDeviceBuffer< T >::data(), q3::PlanewaveBasis::fft_wave(), q3::FFTGrid::local_grid_points(), and q3::FFTGrid::total_grid_points().
 1.9.8